Granite Switch 4.1: Chat, Decisions, and Speech from One Endpoint ↗
暂无摘要
PERSONAL TECHNOLOGY READER
经过相关性筛选的 AI 与科技资讯摘要。
暂无摘要
Amazon Elastic Compute Cloud (Amazon EC2) T8i instances are now available in South America (São Paulo). These instances are powered by custom sixth generation Intel Xeon 6 processors, available exclusively on AWS, and built on the latest sixth generation AWS Nitro cards. T8i instances deliver up to 30% better price performance compared to previous generation T3 instances, and offer four sizes: nano, micro, small, and medium. These instances are designed for workloads requiring low to moderate CPU utilization, including data processing, login gateways, small databases, batch processing, event driven functions, CI/CD pipelines, microservices, and low traffic websites. T8i instances deliver up to 70% higher compute performance, 1.25x higher network bandwidth, and 2.4x higher EBS bandwidth compared to T3 instances. They use the same CPU credit system as T3 with Standard and Unlimited modes, so existing T3 customers can upgrade to T8i and immediately benefit from better price performance, enabling them to lower their TCO. For customers new to AWS or migrating from on-premises, T8i instances provide one of the most cost-effective entry points to run a variety of workloads. T8i.micro and T8i.small are available under the AWS Free Tier . T8i instances are available in US East (N. Virginia, Ohio),
AI, agents, voice, and physical controls are shifting software development from operating tools to expressing intent—and helping developers stay focused on building. The post The next developer interface is ambient intelligence appeared first on The GitHub Blog .
Introducing the Rosalind Academic Plan, offering eligible academic labs sponsored access to GPT-Rosalind and tools to advance life sciences research.
Amazon DynamoDB Streams now supports timestamp-based stream processing, enabling you to begin reading stream records from a specific point in time. Previously, you could only start from the oldest retained record (up to 24 hours old) or from new records written after you start consuming the stream. Now, you can supply a timestamp and begin processing at the first record written at or after that time using the AT_TIMESTAMP shard iterator type. Timestamp-based stream processing can be used with the Amazon Kinesis Client Library (KCL) through the DynamoDB Streams Kinesis adapter. It helps you avoid reprocessing entire retained streams or missing records when resuming stream consumption, supporting common use cases such as recovery after an interruption, data replay for debugging and auditing by reading from a specific point in the past, skipping a backlog by resuming from a recent timestamp near the latest records, and synchronizing after a restore by beginning at the export timestamp following a point-in-time recovery (PITR) export. Timestamp-based stream processing is available in all commercial AWS Regions, the AWS GovCloud (US) Regions, and the China Regions. There is no additional charge for this feature beyond standard GetRecords API request charges. To get started, see Amazon DynamoDB
Today, AWS announces the general availability of the AWS Lambda Durable Execution SDK for Go, enabling Go developers to build resilient, long-running workflows using Lambda durable functions. With this SDK, developers can create multi-step applications like infrastructure automation, deployment rollouts with approval gates, and pipelines that call AI models and pause for human review directly in their Go code without implementing custom progress tracking. Lambda durable functions extend Lambda's event-driven programming model with operations that checkpoint progress automatically and pause execution for up to an year when waiting on external events. The AWS Lambda Durable Execution SDK for Go provides a native Go experience for building with Lambda durable functions. It includes steps for progress tracking, callback integration for human and agent-in-the-loop workflows, durable invocation for reliable function chaining, and waits for efficient suspension. The SDK works with the Go tools developers already use. Developers add it to a Go module with go get and deploy their function as a single static binary on the provided.al2023 runtime, like any other Go function on Lambda. Before deploying, they can locally test complete workflows on their own machine with the durabletest package, without requiring network access or AWS credentials, and use the
Meta's Muse Spark Open is now available on Amazon SageMaker JumpStart, expanding the portfolio of foundation models available to AWS customers. This coding-optimized open-weight model from Meta is purpose-built for agentic coding workflows, bringing multi-step reasoning and tool calling to enterprise software engineering on AWS infrastructure. Muse Spark Open is designed for long-running coding agents and multimodal engineering workflows. Built on a Mixture-of-Experts (MoE) architecture with 816B total parameters and 42B active per token, it delivers the capacity of a very large network while keeping per-token compute closer to that of a much smaller dense model. The model holds a 1M-token context window, enabling it to ingest an entire project—including dependencies, legacy code, and thousands of files—without splitting tasks into smaller pieces. It accepts text, images, documents, audio, and audio-video as input and generates text output. Trained on real developer workflows such as multi-file refactors and long debugging sessions, it plans, acts, observes results, and self-corrects over long horizons rather than making single tool calls. SageMaker JumpStart offers two variants: BF16 (Muse-Spark-Open-816B-A42B) and NVFP4 quantized (Muse-Spark-Open-816B-A42B-NVFP4), with the NVFP4 variant requiring roughly a quarter of the memory for cost-efficient deployment. With SageMaker JumpStart, customers can deploy Muse Spark Open with
Put native GitHub features to work to review outside collaborator access and archive stale repositories. The post Staying Evergreen: How we automated secure access and repo hygiene in a shared org appeared first on The GitHub Blog .
AWS HealthOmics now supports sharing VPCs across accounts, enabling your workflows to access resources in Amazon Virtual Private Clouds (VPCs) managed by other AWS accounts with AWS Resource Access Manager (RAM). AWS HealthOmics is a HIPAA-eligible service that helps healthcare and life sciences customers accelerate scientific breakthroughs at scale with fully managed bioinformatics workflows. With shared VPCs, customers can centralize networking administration by sharing subnets and security groups from a single VPC across multiple accounts in their organization, and HealthOmics then places each account's workflows directly into those shared subnets. With cross-account VPC sharing, multiple accounts run inside one centrally managed VPC, instead of duplicating endpoints across VPCs. Workflows in participating accounts can access data privately without separate VPC peering connections or duplicated VPC endpoints. Previously, customers with centralized networking had to create separate AWS PrivateLink VPC endpoints in each VPC and maintain individual route tables using VPC peering. Cross-account VPC sharing reduces infrastructure overhead and simplifies network management for organizations with centralized networking while allowing researchers and developers to run bioinformatics workflows in their own accounts. Shared VPCs is available in all Regions where AWS HealthOmics is available: US East (N. Virginia, Ohio), US West (Oregon), Europe (Frankfurt, Ireland,
Amazon Time Sync Service introduces support for microsecond-accurate time on 135 additional EC2 instance types—spanning 12 instance families—in all commercial regions. Built on Amazon's proven network infrastructure and the AWS Nitro System, microsecond-accurate time and nanosecond-precision hardware timestamps leverage the reference clocks running in the Nitro System directly, enabling customers to easily order application events, measure 1-way network latency, and increase distributed application transaction speed. The newly supported families include eight Gen8 families (C8a, C8i, C8i-flex, C8id, M8i, M8i-flex, R8a, and X8i) and four Gen9 families (C9g, C9gd, M9g, and M9gd). Starting today, customers can access microsecond-accurate time on these additional instance types by creating a Precision Time Placement Group (PTPG), a new placement strategy that allows customers to launch instances with Precision Time Protocol hardware clock (PHC) enabled. Customers that require both low network latency as well as precision time can associate a PTPG with their Cluster Placement Group (CPG), so that their low-latency workloads also benefit from microsecond-accurate time. For more information, refer to the Amazon Time Sync Service documentation .
Anthropic announces updates to embedding independent evaluators
A new beginning for Windows PCs starts tomorrow with the launch of NVIDIA RTX Spark — one PC built for creators, gamers and AI agents. All are invited to celebrate with NVIDIA and partners at launch events around the world. Share Your Spark Every PC has a story. What was your first Windows PC, and […]
Today, AWS Transform for full-stack Windows modernization adds support for cross-region deployment of converted Amazon Aurora PostgreSQL databases and is available in seven additional AWS Regions. Together these changes give customers more control over where their modernized databases are deployed after SQL Server modernization, supporting data residency, latency, and disaster recovery requirements. Customers can upload SQL Server Database Design Language (DDL) files and set a target AWS Region in the transformation plan to convert the database and deploy the resulting Aurora PostgreSQL cluster to a different AWS Region. The same workflow makes dependent .NET applications PostgreSQL compatible, updating connection strings and ADO.NET and Entity Framework data-access calls. With this expansion, AWS Transform for full-stack Windows modernization is now available in the following Regions: US East (N. Virginia), Europe (Frankfurt), Europe (London), Asia Pacific (Mumbai), Asia Pacific (Seoul), Asia Pacific (Tokyo), Asia Pacific (Sydney), and Canada (Montreal). To get started, you can go to AWS Transform product page or see AWS Transform for full-stack Windows documentation .
Starting today, Amazon MSK Connect and the AWS Glue Schema Registry are available in the AWS European Sovereign Cloud (Germany) region. Together with Amazon MSK Standard brokers, already available in the region, these launches give customers running streaming workloads on the AWS European Sovereign Cloud a more complete set of tools to build, connect, and govern their Apache Kafka applications. MSK Connect lets you run fully managed Kafka Connect clusters with Amazon MSK - deploy, monitor, and scale connectors that move data between Apache Kafka and external systems like databases, file systems, and search indices, with no infrastructure to provision, automatic scaling, and pay-as-you-go pricing. Complementing it, the AWS Glue Schema Registry - a serverless, free feature of AWS Glue - lets you validate and control the evolution of streaming data using Apache Avro, JSON, and Protobuf schemas. Acting as a centralized repository for data format and structure across decoupled applications, it reduces data validation logic, cross-team coordination, and downstream failures, and integrates with C# and Java applications built for Amazon MSK , Amazon Kinesis Data Streams , Amazon Managed Service for Apache Flink , and AWS Lambda . To get started, visit the Amazon MSK Developer Guide and the

Accelerating the search for novel antimicrobial peptides using Google Antigravity for Science.
Neural networks are clean
Starting today, Amazon RDS for PostgreSQL 19 Release Candidate 1 (RC1) is available in the Amazon RDS Database Preview Environment , allowing you to evaluate the pre-release of PostgreSQL 19 on Amazon RDS for PostgreSQL. PostgreSQL 19 RC1 focuses on stability, with bug fixes and improvements from the Beta 4 testing period. This release improves error handling for complex text-search expressions, hardens parallel autovacuum, and improves reliability of GIN index maintenance. Refer to the PostgreSQL community announcement for more details.. Refer to the PostgreSQL community announcement for more details. Amazon RDS Database Preview Environment database instances are retained for a maximum period of 60 days and are automatically deleted after the retention period. Amazon RDS database snapshots that are created in the Preview Environment can only be used to create or restore database instances within the Preview Environment. You can use the PostgreSQL dump and load functionality to import or export your databases from the Preview Environment. Amazon RDS Database Preview Environment database instances are priced as per the pricing in the US East (Ohio) Region.
Zero-knowledge proofs can verify computing results without rerunning workloads or exposing sensitive data. Magnetar helps bring them into the mainstream with support for standard programming languages, major speed gains, and quantum-resistant security. The post Proof-based general-purpose computing with Magnetar appeared first on Microsoft Research .

NVIDIA today released Nemotron 3.5 Super VL, an open 120-billion-parameter model that delivers the fastest task completion and highest accuracy for specialized always-on agents. Joining it are two new edge models: Nemotron 3.5 Bolt 74B-A9B 24GB, optimized to balance intelligence and speed per GB for local agentic workloads, and Nemotron 3.5 Bolt E4B 4GB, optimized […]
Anthropic tells investors quarterly revenue up nearly 50% to $16.8bn ahead of IPO The phrase "told investors" appears four times in this FT article, which reports on Anthropic's day of hosting investors on Wednesday. Lots of details in here from " people with knowledge of the matter ". Key things I learned from the article: Q1 revenue (Jan/Feb/Mar) was "about $4.8bn" Q2 (Apr/May/Jun) was $11.5bn Q3 (Jul/Aug/Sep) was $16.8bn In Q3: $1.70 in revenue for every $1 spent on "computing power" Adjusted operating margins (excluding stock-based compensation) were 11% This point about distillation is worth quoting in full (highlight mine): The start-up has also clamped down on “distillation” — a controversial practice whereby rival AI labs train their models on the outputs of more advanced ones. When rival companies “distil” their models from Anthropic’s models, that involves heavy usage and spending. Anthropic told investors on Wednesday distillation accounted for 5 per cent to 7 per cent of revenue and that they had cut it back “materially” in the third quarter of the year, said four people with direct knowledge of the matter. Napkin maths says that if distillation was 5% of their Q2 revenue (before they cut it back in
Dial in the next gaming session this GFN Thursday. New NVIDIA DLSS 4.5 controls give GeForce NOW members more choice over how supported games look and perform in the cloud, even without the latest hardware. Then, step into the Shroud as Keen Games’ Enshrouded leaves early access with its 1.0 release, or let the bolts […]
Celebrate Teachers’ Day with AI for Educators in Brazilian Portuguese and see how Study Mode can help teachers support active, step-by-step learning.
State-of-the-art probabilistic forecasting in four sizes (5M–209M params), CPU-efficient, zero-shot ready.
Much of today’s scientific progress begins with computation. But turning accelerated computing’s potential into scientific progress — modeling climate systems, designing molecules, simulating materials and more — depends on more than breakthrough technology. Especially for smaller labs, early-career scientists or science-based startups, the hardest part of research can be everything that comes before the science: […]
暂无摘要
The Nordic countries have become the European leader in unicorn startup density, producing the most emerging companies valued at $1 billion or more per capita on the continent. Now, a new chapter for the region is unfolding as countries race to build one of Europe’s most consequential technology ecosystems. The many computing advancements already underway […]
arXiv:2610.14136v2 Announce Type: new Abstract: Iterative sampling in diffusion models can lead to error accumulation due to exposure bias. The denoiser is trained on real images interpolated with noise, but at inference its inputs are constructed from its own imperfect predictions from the earlier steps, something it has never seen at training time. This might be one reason diffusion models often struggle without additional help, such as CFG. We introduce a correction step for diffusion models which attempts to reduce this training-inference gap. The corrector takes the base model's prediction as input and is trained against the same ground-truth target. This makes correction an explicit learning task, with training inputs provided by the base model. During sampling, at each denoising step, we iteratively refine the denoiser's clean-sample prediction. This allows us to correct predictions at intermediate denoising steps, preventing early artifacts from persisting into the final sample. Although the corrector is trained only on predictions from the base denoiser, it can be applied repeatedly to its own outputs at inference for better results. This simple framework leads to substantial improvement in sample quality while largely preserving diversity. We evaluate our method across DiT, SiT, and JiT. Our method substantially improves
arXiv:2610.18881v1 Announce Type: new Abstract: Voice agents built on large language models (LLMs) now handle customer calls, but in regulated applications completing the task is not enough: the agent must follow a conversational flow set by law. In debt collection, it must confirm it is speaking to the debtor before mentioning the debt, identify itself and the creditor, state the amount, and avoid prohibited language. Every creditor turns these rules into its own procedure and revises it. We ask whether a small, self-hosted policy can be trained once and then follow regulated procedures it has never seen. One machine-readable specification per deployment, FlowSpec, generates the policy instruction, gates the tools, supplies the supervision and defines the tests; the agent speaks only approved catalogue sentences. We fine-tune a 9-billion-parameter model on 2,506 conversations from 297 randomized procedures and evaluate a Thai outbound-call agent on four unseen deployment procedures (three debt collection, one non-debt), one from a wholly withheld lineage. Documented checks, fixed by the procedure, rise from 67--71 percents to 93--100 percents, while grounded checks, fixed by the conversation, already pass at 97--100 percents before training; scenario pass rate rises from 15/43 to 40/43. An audit of the shared specification finds
arXiv:2610.19003v1 Announce Type: new Abstract: Abstractive summarization remains challenging across languages, where linguistic quality and factual consistency may diverge, particularly in low-resource settings. We present a standardized zero-shot benchmark of eight closed-source and open-weight LLMs on size-matched English and Bengali XL-Sum test sets. Our evaluation combines lexical and semantic metrics with reference-free factuality verification and multidimensional LLM-as-a-Judge assessment, providing a comprehensive analysis of both surface-level quality and factual reliability in multilingual summarization. Results reveal substantial cross-lingual variation: GPT-5.6 Luna leads several English lexical metrics but does not maintain the same advantage in Bengali, where LLaMA 3.3 70B achieves the highest ROUGE and BLEU scores. Gemini 2.5 Flash obtains the highest observed Bengali factuality score. Furthermore, evaluation methods produce different model rankings, highlighting the limitations of relying on a single metric for multilingual summarization assessment. These findings demonstrate that strong English summarization performance does not necessarily transfer to Bengali and emphasize the need for comprehensive evaluation frameworks for low-resource languages.
arXiv:2610.19026v1 Announce Type: new Abstract: Sparse attention reduces the KV-cache traffic that dominates long-context LLM decoding, but practical methods largely operate at coarse granularity. Token-level selection offers finer control, yet presents two challenges: low-dimensional scoring may lose query--key structure needed for accurate ranking, while gathering scattered selected tokens can offset the resulting latency benefit. We introduce Joint Subspace Sparse Attention (JSSA) to address both challenges. For selection quality, JSSA learns a shared low-dimensional query--key subspace by minimizing token-score preservation error. We upper-bound the resulting non-convex objective with a tractable marginal objective that admits a closed-form spectral solution; direct refinement of the exact objective provides no measurable improvement in the tested settings. For execution efficiency, we develop a gather-free token-level indexed-attention kernel that supports distinct per-KV-head selections under the standard grouped-query attention (GQA) KV-cache layout. Across standard GQA, hybrid sliding-window/global attention, and Multi-head Latent Attention (MLA) models, JSSA consistently remains close to full-KV accuracy while avoiding the substantial generation-length inflation and architecture-dependent failures observed with competing methods. On an NVIDIA B200 GPU, JSSA achieves up to $6.43\times$ the decoding throughput of full-KV attention at 128K context. JSSA achieves reasoning accuracy comparable to model-native DSA without model training and reaches 96--99\% of
arXiv:2610.19028v1 Announce Type: new Abstract: Science fiction is widely credited with unsettling gender. This article asks whether that holds at the linguistic level, in how readily gendered reference gives way to its counterpart, a neutral term, or other social category, and whether it separates the genre from general fiction. It does so by masking man/men, woman/women, and person/people across same-period science fiction and general fiction corpora and classifying RoBERTa's five likeliest substitutes by gender. Retention and displacement are permutation-tested over five resampling rounds, and the underlying sentences are read closely. Both corpora cross the gender binary in both directions, but unequally: where woman is masked, the model predicts a masculine term about twice as often as it predicts a feminine term where man is masked. Each mismatch marks a statistical surprise, a word the corpus did not expect there. Against this shared pattern, science fiction shows greater gender permeability than the general fiction corpus, placing man in feminine contexts more often than general fiction while the reverse rate holds steady. Its degendering tendency is stronger too, drawing both gendered terms toward the neutral. Beyond the binary, a masked woman also draws substitutes naming a social category and no gender far
arXiv:2610.19048v1 Announce Type: new Abstract: Record linkage and demographic inference from names are routine demands in social science. Most approaches to these problems require labeled training data that are difficult or costly to acquire. I show that pre-trained language models perform both tasks accurately without requiring task-specific training. For record linkage, I introduce EnsembleLink, an algorithm that uses pre-trained embeddings alongside string-based scorers to retrieve a short list of candidates and then identify the likeliest matches. EnsembleLink matches or exceeds the performance of most prior approaches while generalizing across scripts and formats that those methods are unable to handle. For ethnicity inference from names, I show that large language models (LLMs) achieve up to 83.8% accuracy on U.S. voter files, compared to 78.0% for name-supplemented BISG. Open-weight models offer reproducible implementations that approach these models in accuracy. Moreover, LLMs are able to infer group membership for religious, caste-based, and other ethnic group categories outside of the United States, and reduce bias in downstream estimates of geographic racial gaps. Where pre-training encodes the world knowledge required by each task, task-specific labels add less information.
arXiv:2610.19095v1 Announce Type: new Abstract: Chatbot Arena ranks language models with the Bradley-Terry model, which gives each model one score and so assumes Luce's choice axiom. Choice theory predicts where this fails: near-copies are told apart more decisively than their scores imply. On 1.8 million Arena votes, votes between versions of one model are 1.37 times as decisive as Bradley-Terry predicts, between sizes of one generation 1.26 times and between models of one lab 1.12 times; a release a year later gives consistent multipliers, and the effect survives alternative tie treatments, prompt subsets and topics, and timing checks. How alike two models' answers are worded and formatted tracks the effect. A correction with four to six parameters predicts held-out votes better than Bradley-Terry and than models with hundreds of parameters, mostly by modelling ties; frozen and carried to new releases in a test fixed in advance, its gains are concentrated in ties, and better head-to-head odds are not established. The leaderboard order barely moves. With language-model judges and three-answer menus, a near-copy takes votes mostly from its twin when choices are pooled over prompts (log-odds shift +0.10, 95% interval 0.05 to 0.16); within a prompt the shift is smaller and
arXiv:2610.19113v1 Announce Type: new Abstract: In-context learning (ICL) allows language models to adapt their behavior from instructions and demonstrations in a prompt, but accuracy alone does not reveal how contextual information controls their predictions. We study the acquisition and trainability of ICL with a controlled diagnostic that separates copying a nearby demonstration from integrating information across the prompt. Across 17 models, about a third prefer the copied answer, a few are undecided, and the rest prefer the rule-consistent answer, which goes with higher accuracy and with control by the requested value rather than the closest conflicting example. Checkpoint analyses show that models begin prioritizing task-relevant prompt tokens over conflicting examples long before their accuracy improves beyond chance level. In matched training experiments, synthetic documents that define endings and then query them shift models toward compositional responses on the controlled diagnostic, whereas fine-tuning on definition exercises built from rewritten real documents improves accuracy when prompts reassign label meanings. The results suggest that ICL is not acquired as a single, uniform capability. Instead, prompt control, answer preference, construction without candidates, and transfer can develop along distinct trajectories.
arXiv:2610.19118v1 Announce Type: new Abstract: Emerging decision models such as JEV provide typed interfaces that map task instructions and observations directly to choices, judgments, and scores. As these models are increasingly used for automated decision-making, understanding their reliability under adversarial manipulation becomes critical. We introduce DecisionRobust, a benchmark for systematically evaluating the robustness of decision models across textual and visual inputs. Our benchmark covers practical decision-making scenarios and a diverse suite of attacks, including semantics-preserving text perturbations, image perturbations, and prompt injection in both modalities. We curate evaluation sets through external validity checks and cross-model candidate selection. We evaluate 30 model configurations on text tasks and 17 on vision tasks, including 24 and 12 held-out models, respectively, that are excluded from candidate selection. Our experiments reveal several key findings. First, attacks expose vulnerabilities beyond the models used for construction and selection, although optimized image perturbations transfer weakly to many targets even with multiple surrogates. Second, relative model robustness varies across tasks and attack types, and resistance to input perturbations does not necessarily imply resistance to prompt injection. Third, label-consistency checks substantially reduce measured attack success across text and image settings, highlighting the importance of validating apparent failures. The benchmark is
arXiv:2610.19134v1 Announce Type: new Abstract: Feature distillation is usually expected to add to logit distillation. We find that this expectation does not hold for two common feature losses in compact multilingual automatic speech recognition (ASR), and analyze why through their gradients. The gradient of a projection-based loss is orthogonal to the task gradient, while that of Centered Kernel Alignment (CKA), a similarity-based loss, is weakly aligned with it. CKA lowers the word error rate (WER) on non-English languages, but at the expense of data-rich English. Three loss-level remedies (one trained, two probed) all fall short, and the CKA gradient overlaps with the subspace English uses in the shared encoder by 97.5% to 99.5% (about 81% by chance). Guided by this diagnosis, we propose CAFE (Confined-Adapter Feature distillation), which confines the CKA gradient to adapters that English bypasses, addressing the trade-off in the parameters rather than in the loss. On the Open ASR Leaderboard, CAFE lowers the average WER from 8.55% to 8.02%, beats an adapter-only capacity control at 8.51%, and makes English more stable across checkpoints. At 254M parameters, it trails the 0.6B teacher by 2 WER points and is competitive with much larger models across 48 test sets in
arXiv:2610.19164v1 Announce Type: new Abstract: Mixed methods research offers established strategies for integrating qualitative and quantitative evidence, but less guidance for integrating two computational representations of the same qualitative corpus. This methodological study introduces Parallel-Then-Integrated (PTI), a four-step procedure for explicit and traceable integration. We present PTI using 1,203 interview paragraphs from 29 mothers in Nepal. The two representations were ontology-guided Patient Voice (PV) coding with PVminer and data-driven themes generated through non-negative matrix factorization (NMF). A theme-complete crosswalk documented convergence, divergence, and preprocessing-sensitive differences. Depression status, based on Patient Health Questionnaire-9 (PHQ-9) scores, served as a secondary external anchor for exploratory association checks. PTI provides a structured approach for integrating computational representations of qualitative text within mixed methods research.
arXiv:2610.19166v1 Announce Type: new Abstract: Meta-evaluation of text generation metrics and LLM-judges is primarily conducted using metric-human correlations. However, prior work has shown that correlation is not an appropriate estimate of a metric's evaluation capability and can be unstable across evaluation settings, such as different datasets or languages. Therefore, we propose a regression-based meta-evaluation of metrics that learns on calibrated metric outputs to predict human ratings. We ground this measurement relative to a trivial constant-mean baseline and human agreements to provide a comparable measure of metric capability across evaluation settings. To test our meta-evaluation framework, we developed a large-scale multi-lingual style-personalized text generation (SPTG) benchmark, collecting multiple annotations across 10 topologically diverse languages and four evaluation dimensions, each with varying degrees of subjectivity. We meta-evaluated 32 metrics from three style evaluation paradigms (string-based, embedding-based, and LLM-judges) and their ensembles over these 40 evaluation settings. Our analysis revealed that even simple string- and embedding-based measurements can match strong LLM-judges when calibrated to human ratings. We also identified characteristics of human annotations that determine metric performance, as well as conditions under which a metric ensemble outperforms its individual constituents.
arXiv:2610.19184v1 Announce Type: new Abstract: Harness optimization improves LLMs by refining reusable prompts and scaffolding, yet requires further adaptation for program generation tasks such as text-to-SQL and text-to-Python. Existing methods often rely on LLM reflectors to propose harness updates, which can fix observed failures but also disrupt previously correct behavior. Text-to-code tasks offer a natural way to mitigate this issue: we can execute generated outputs, allowing us to evaluate and verify the effects of proposed updates directly. Building on this signal, we introduce \textsc{HERO} (\textbf{H}arnessing \textbf{E}vidence for \textbf{R}efinement and \textbf{O}ptimization), which combines offline and test-time harness optimization. At the first stage, \method{} learns reusable prompt updates from execution-verified successes and failures and validates candidate revisions before adoption. At test time, we treat the generated code as an instance-specific harness and refine it using execution feedback. Across four SQL, Cypher, and Python benchmarks, \method{} achieves the best offline performance, improving pass@1 by \(7.6\) points over the initial prompt, while test-time refinement adds another \(2.0\) points and improves execution efficiency.
arXiv:2610.19185v1 Announce Type: new Abstract: Evaluation of large language models (LLMs) remains largely pre-scientific: it involves many design decisions, with little guidance on how to make them. These choices can substantially affect measured performance and, consequently, decisions about subsequent pretraining. To identify effective evaluation setups, we investigate 8 aspects, such as task formulation or the number of in-context examples. We compare the setups using three widely-used signal criteria, repurposed as normative meta-measures: monotonicity, non-randomness, and ranking consistency of the evaluation scores across intermediate checkpoints. In an early pretraining scenario, we evaluate these setups on 26 monolingual 2B-parameter models trained on different types of data, using 80 tasks in four languages. We also examine the setups on three larger LLMs ($\geq$7B) in the same four languages and explore how the preferred setups change with model scale. Our results yield concrete recommendations: some choices, such as the use of multiple prompts, are consistently useful, whereas others, such as task formulation, depend on model scale. More generally, our framework serves as a recipe for the choice of evaluation setups in new scenarios.
arXiv:2610.19190v1 Announce Type: new Abstract: Many sentiment datasets use one annotator for each item, so the test labels show the conventions of that person. We build a Nepali benchmark from two annotators who labelled the same sentences blind. They labelled 5,614 sentences from tweets of Nepali public figures on a five-point scale. We keep only the 3,189 sentences where both give the same polarity. On the three-class benchmark, NepBERTa with a fixed tokenizer gets a macro-F1 of 0.877 and IndicBERTv2 0.867. Three commercial large language models (LLMs) get 0.882 to 0.896 zero-shot, and these differences are not significant. On the five-point scale, 766 sentences have two adjacent labels, for example Pos and SPos. We accept both labels and train on both. On this task, Claude Opus 5.5 beats the best encoders by 0.10 to 0.12 macro-F1. A tokenizer audit adds a second result. The default tokenizers of three Nepali BERT models delete the non-spacing Devanagari vowel signs and the virama. When we restore the marks, macro-F1 increases by 0.084 for NepBERTa but decreases by 0.095 for a model pretrained on stripped text.
arXiv:2610.19206v1 Announce Type: new Abstract: While work on LLM-based regression has largely focused on scalar prediction, multi-output text regression remains less explored. We present DualView, a parameter-efficient approach to leverage LLMs for multi-output text regression. \method{} first extracts broad and output-specific representations from a frozen LLM, then uses a dual-branch architecture to produce the full score vector. Across five heterogeneous regression tasks and eight LLMs (up to 122B), DualView outperforms seven supervised regression baselines while requiring 82--1842 times fewer fitted parameters than the three strongest baselines. These improvements extend across individual output dimensions and persist even with limited training data. Notably, DualView using a smaller open-weight LLM can outperform unsupervised prediction with Gemini 3.1 Pro. Controlled ablations show that broad and output-specific evidence provide complementary predictive benefits, while lightweight shared predictors achieve strong performance with fewer trainable parameters.
arXiv:2610.19210v1 Announce Type: new Abstract: Transformers are efficient to pre-train at scale because attention permits parallel computation across sequence positions, but long-context inference requires increasingly large KV caches. Efficient recurrent alternatives reduce the asymptotic complexity of inference, but their sequential dependence limits token-wise parallelism during training, making them harder to scale. Further, the current paradigm of extending long context tasks creates competing notions of retaining information precisely and keeping long-context inference efficient. To address this gap, we introduce Titan-Llama, a post-training method for retrofitting attention-based language models with a hierarchical memory architecture that updates parameters at test-time. Titan-Llama applies a blockwise attention mask and preserves full-fidelity attention over recent tokens while compressing historical context into recurrent, fixed-size neural memory modules (NMMs). Our formulation allows pre-trained attention layers to be replaced without training a new language model from scratch. On Llama-3.2-1B-Instruct, Titan-Llama raises accuracy over segmented attention windows from 23.87\% to 40.51\% on QuALITY and from 14.50\% to 40.75\% on LongHealth. Inference benchmarks show more than 20\% faster prefill, 37\% faster decode at medium context lengths, and 24\% lower steady-state decode memory usage in the evaluated configurations. Together, these results demonstrate that incorporating memory architecture mechanisms that utilize test-time training effectively
arXiv:2610.19231v1 Announce Type: new Abstract: Transformer language models develop attention heads that specialize in syntactic relations, for example, attending from verbs to their subjects. Do these heads play a causal role in the model's syntactic predictions? Evidence for such a role is mixed to negative: even when we force these heads to attend to a distractor noun other than the subject, the model's syntactic predictions are still more consistent with the subject than with the distractor. Interventions on specialized syntax heads had a significantly stronger effect on syntactic predictions than interventions on random heads, but only in one of the two measures we propose.
arXiv:2610.19247v1 Announce Type: new Abstract: Transformers are intuitively considered to be efficient at copying from their inputs. We actually show that the ability of LLMs to copy in context can be improved through explicit modeling. We propose Copy-Paste Language Models (CPLMs), which add a lightweight Copy-Paste head to the conventional language modeling (LM) head. CPLMs improve training efficiency, downstream performance, and offer new operating points in long-context and retrieval setups. We validate our approach by pretraining models from 135M to 1.7B parameters, showing improvements across all scales and backbones with negligible training and inference overheads. We explain the success of CPLMs by showing that they partially mitigate the LM head gradient bottleneck through an alternative gradient path.
arXiv:2610.18877v1 Announce Type: new Abstract: Time-series language models typically align numerical signals with language using labels, captions, or question-answer pairs. Although such supervision encourages linguistic representations, it does not explicitly require them to preserve information about how the underlying time-series signal evolves. We introduce forecast grounding, a pretraining principle that requires language-aligned time-series representations to remain predictive of the future evolution before they are adapted to downstream tasks. We instantiate this principle in LOTUS, which divides each time-series channel into non-overlapping patches and maps them into the LLM embedding space. It then predicts the next patch from the LLM hidden states of the time-series tokens, encouraging the learned representation to retain temporal information. To capture both temporal changes and periodic patterns, we also propose a temporal-spectral patch representation that combines each raw time-series patch with its spectral representation before mapping it into the LLM embedding space. Across three language model backbones and six downstream evaluation datasets, LOTUS achieves the best average performance with minimal trainable parameters, reaching 59.91% accuracy and outperforming the strongest matched baseline by 3.36%. Our representation analyses further show that LOTUS uses the numerical input and preserves temporal structure in its learned patch representations. These results establish
arXiv:2610.18878v1 Announce Type: new Abstract: Post-training reasoning LLMs often requires making a tradeoff between costly supervision and compute inefficiency: supervised finetuning typically requires reasoning traces, which is data inefficient since in many applications one only has prompt-answer tuples and lacks the groundtruth chain-of-thought (CoT) sequence. On the other hand, reinforcement learning (with verifiable rewards, for example) can operate without CoT data but it is much more compute-inefficient since it requires multiple autoregressive completions per optimization step, none of which are guaranteed to give a non-zero policy gradient. In this work we explore a middleground, a self-distillation technique that uses answer-only data, treating CoT as latent variables. This relies on training a partner ``inverse reasoning LLM" that generates the original's reasoning traces conditioned on the answer. The inverse model is trained once and reused across incoming batches of answer-only data, with all generation happening offline and up front, making the approach particularly suited to continual post-training. Using Qwen3-0.6B on the Countdown and GSM8K tasks, we show that after GRPO training has saturated, a single offline distillation round from the inverse model roughly doubles pass@1 on hard prompts and, on Countdown, outperforms rejection-sampling self-distillation on every hard-tail metric at every mix ratio
arXiv:2610.18879v1 Announce Type: new Abstract: Protein function annotation operates over an expanding label space, making class-incremental learning (CIL) a natural framework for incorporating newly discovered functions without full retraining. Yet existing CIL methods have been developed largely in vision and have not been systematically evaluated over frozen protein representations. We conduct a controlled benchmark of nine representative CIL methods across five sequence-, structure-, and sequence--structure-based protein encoders and two enzyme function datasets at different scales, while keeping the encoders frozen and evaluation settings consistent across representations. We find that no method transfers reliably across encoders, and that these failures persist across alternative phase constructions. Diagnostic analyses reveal that this instability arises from weak gradient-based stability signals, substantial heterogeneity in embedding geometry, and covariance assumptions whose appropriate capacity changes with both dataset scale and encoder. These findings suggest that the representation itself should be treated as a central component of continual-learning design rather than a passive feature extractor. More generally, reliable protein CIL will require encoder-aware methods that adapt their statistical assumptions and capacity to the geometry of the representation on which they operate. Code is available at https://github.com/zygao930/ProteinCIL.
arXiv:2610.18880v1 Announce Type: new Abstract: High-throughput perturbation screens increasingly use machine-learning models to predict the effects of gene combinations that were never measured. A difficult case arises when both genes in a test pair were seen individually during training, but their combination was not. In this setting, standard OOD methods often fail because neither gene appears unfamiliar on its own. We therefore compare each model prediction with a simple additive prediction obtained by summing the two observed single-gene effects. The difference between them, which we call additive disagreement (AD), measures how much extra interaction effect the model introduces for an unseen combination. Across eight prediction methods and three Perturb-seq datasets, specialised neural predictors do not consistently outperform this simple additive baseline. More importantly, predictions with larger deviations from the additive baseline tend to have larger errors. Conventional output-based and embedding-based confidence signals are inconsistent across datasets and models, whereas AD remains informative across all evaluated compositional settings. We further study how this signal can guide decisions in an agentic perturbation-screening workflow. The code is available at https://github.com/zygao930/OOD.
arXiv:2610.18883v1 Announce Type: new Abstract: Token-selection methods for on-policy distillation (OPD) prioritize student-visited positions using diverse signals, including uncertainty, teacher-student disagreement, and mismatch direction. We instead derive token importance from the distillation objective itself: how much can each position's loss decrease under an equal local KL budget on the student's predictive distribution? The answer is the utility $s_t=g_t^\top F_t^\dagger g_t$, where $g_t$ is the logit gradient and $F_t$ is the categorical Fisher matrix. For reverse-KL it equals the student-weighted variance of the student-teacher log-probability ratio, and for forward-KL it equals the Pearson $\chi^2$ divergence, so the appropriate utility follows from the choice of objective. On shared training checkpoints, several independently motivated criteria, including student entropy, KL disagreement, and TIP, concentrate their importance on nearly the same positions as the derived utility at a 50\% selection fraction, while diverging at stricter fractions and for direction-specific criteria. We instantiate the utility as Fisher Utility Weighting (FUW), a continuous, mean-normalized token weighting. Across seven mathematical reasoning benchmarks and three Qwen3 student-teacher pairs, FUW improves over matched uniform OPD under both reverse-KL (1.35-4.0 macro points) and forward-KL (1.08-2.71 macro points), and is competitive with existing selective methods using a single closed-form score derived from
arXiv:2610.19011v1 Announce Type: new Abstract: The Practical Molecular Optimization (PMO) benchmark standardized evaluation in molecular optimization, but it is built on simple property-based oracles that do not capture structure-based drug design. As the field has moved to docking-based objectives, evaluation practice has become unstandardized, and different methods report results on different docking tasks, often without a shared protocol for fair comparison or sample-efficiency constraints. To address this, we introduce Practical Molecular Optimization for Docking (PMO-Dock), a benchmark and protocol for docking-based optimization consisting of 25 tasks covering hit generation, lead optimization, and a new specificity task requiring strong on-target binding while penalizing off-target interactions. The protocol separates model development from final evaluation: validation tasks are used for hyperparameter tuning, and test tasks are held out for final evaluation and are not used during development. Evaluation on the test tasks is done under a strict oracle budget to reflect realistic drug-discovery settings. We benchmark four diverse high-performing methods spanning different optimization paradigms, Saturn (reinforcement learning), GenMol (discrete diffusion), Genetic-guided GFlowNet, and ChemLlama (LLM-based evolutionary search). Our results show no universally best method across tasks, additional analyses of hyperparameter transfer (cross-task and cross-category) and sensitivity show that transfer is often limited and
arXiv:2610.19013v1 Announce Type: new Abstract: Current scaling law formulations suggest that increasing the number of unique samples in a dataset improves model performance, while repeated exposure to the same samples provides diminishing value. In this work, we examine this assumption for image self-distillation models. Through systematic experiments across diverse datasets, namely Maxar, SATLAS, Waymo, nuPlan, Ego4D, ImageNet, and YFCC15M, we demonstrate that the effects of sample repetition on downstream performance are non-trivial and dataset-dependent. We identify settings where repeatedly training on a smaller random subset can outperform training on a larger set of unique samples. This finding highlights a limitation of existing scaling laws. To address this gap, we propose a modified version of a Chinchilla-style scaling law that explicitly accounts for two factors: the number of unique samples and repetition per sample. This formulation provides a framework for understanding data-compute trade-offs and improves prediction in some regimes where repetition plays a central role, although its benefits are not consistent across datasets. Finally, we examine how subset selection and augmentation affect downstream performance.
arXiv:2610.19015v1 Announce Type: new Abstract: Real measurements are too limited to train an accurate indoor pathloss predictor that works across a wide range of buildings. Large-scale synthetic pretraining offers a way forward, but real building layouts are also scarce, and accurate ray-tracing simulators are slow, expensive, and often proprietary. We address both problems by introducing a generator that automatically creates diverse indoor layouts and a fast, open-source approximate ray tracer that computes radio maps for them. Using this pipeline, we generate 128M synthetic samples, pretrain ResNet-101 and Swin-T encoder-decoders, and fine-tune them on high-quality benchmark data. Despite simulator mismatch, our ResNet-101 model reduces error by 15% on average relative to the best known methods across five indoor radio-map prediction tasks and improves transfer on a small real-measurement dataset. Both architectures show predictable data-scaling trends: power laws fitted on 2M-16M samples predict the mean normalized downstream RMSE at 32M-128M with 3.33% mean absolute percentage error for ResNet-101 and 7.10% for Swin-T. These results show that pretraining on large amounts of cheap simulated data can improve indoor radio-map prediction, even when real measurements and high-quality simulations are limited.
arXiv:2610.19016v1 Announce Type: new Abstract: Regret matching (and its variants) and counterfactual regret minimization are central algorithms in practice for normal-form and extensive-form game solving. Yet these have historically lacked the stronger theoretical convergence guarantees available to optimistic and extra-gradient methods. Recent work introduced IREG-PRM+, a regret matching variant which does have strong theoretical convergence guarantees. However, it relies on a simultaneous, extra-gradient update. IREG-PRM+ is an instance of the more general IR-PRM framework, where empirically optimistic and alternating updates often have better performance. However, the prior extra-gradient analysis does not extend to these cases. We introduce a new approach that covers both settings. For simultaneous and alternating IR-PRM+ in finite two-player zero-sum matrix games, previous-utility prediction recovers the constant-regret and convergence-rate guarantees previously obtained with extra-gradient prediction: external regret bounded independently of T, an O(T^{-1}) average duality gap, and an O(T^{-1/2}) best-current-iterate gap. Moreover, the current duality gap vanishes and the current profile converges to the Nash equilibrium set. The key step bounds the component of consecutive strategy movement not controlled by the existing IR-PRM+ regret inequality using the relative growth of the nondecreasing regret-vector norm rho_t. Coupling this bound across the two players yields recurrences whose effective coefficient
arXiv:2610.19033v1 Announce Type: new Abstract: Low-rank adaptation (LoRA) applies every rank-one component of its update to every token, and mixture-of-experts variants replace this with a learned router that activates a fixed number of components. We argue that the number of components a token needs is a detection question with a classical answer. A token's responses to the rank-one components of a trained LoRA consist of a few large values on a Gaussian noise floor whose width matches that of an untrained adapter, and the floor carries cross-talk rather than adaptation. We introduce SQUELCH, a router-free mixture of rank-one experts that (i) soft-thresholds each token's responses at a multiple of its own robust noise level, so the active rank varies per token; (ii) chooses that multiple for each module by Stein's unbiased risk estimate, so no rank budget is specified; and (iii) replaces the resulting marginal keep-or-drop decisions by one explaining-away step on the value Gram matrix, which suppresses redundant co-active components and recruits complementary ones. SQUELCH adds no trainable parameters to LoRA. We prove that the squelch is within a logarithmic factor of the oracle input-dependent allocation, that the selected threshold is risk-consistent, and that explaining away is a descent
arXiv:2610.19035v1 Announce Type: new Abstract: Pluralistic alignment needs to accommodate diverse preferences under limited human feedback. Using AI simulators to label preference comparisons reduces annotation costs, but variation in simulation accuracy across individuals can leave some people's preferences poorly represented in training. We study how to allocate human feedback across people to construct training data for pluralistic alignment, and how this allocation affects the trained policy. To make this allocation explicit and controllable, we define a social welfare objective over individual supervision utilities that measure label quality. Each query's marginal welfare gain depends on its expected supervision improvement, the recipient's current utility, and application-designated priority. Welfare-Aware Preference Acquisition (WAPA) uses auxiliary reference models to estimate query gains and individual utilities, then selects queries by estimated marginal welfare gain while updating recipient utilities. We prove exact optimality of the acquisition algorithm for the estimated welfare objective under a fixed query budget and model predictions. Experiments on six Roleplay collections and four OpinionQA regions demonstrate improved supervision and controllable allocation tradeoffs. Policy training on four Roleplay collections improves preference prediction for both seen and unseen individuals. When prioritizing a designated group and poorly represented individuals, acquiring human labels for 20% of comparisons
arXiv:2610.19038v1 Announce Type: new Abstract: We study online task assignment with reusable resources. This problem arises in peer reviewer assignment, skill-based call routing, rideshare matching, emergency dispatch, and crowdsourcing: Tasks arrive according to a geometric process and must be immediately assigned to servers that become temporarily busy, yielding rewards that depend on the task-server pair. The goal is to maximize long-run average reward. We cast the problem as a contextual restless multi-armed bandit (CRMAB). We derive an occupancy-measure LP (OCC-LP) that upper-bounds the reward of any work-conserving policy. From its dual we obtain Lag, a closed-form index policy. We introduce a scaling regime in which the number of copies of each server and the number of arrivals per step grow together. This regime yields the first deterministic fluid limit for a contextual bandit. In it, Lag is asymptotically optimal. Finally, we evaluate our algorithms on peer review datasets and call center routing. The Lagrangian index achieves 83-99% of the LP upper bound across all load levels. Moreover, the Lagrangian index policy significantly outperforms the natural greedy assignment scheme, improving reward by up to 12.3% on journal data and 36% on structured synthetic instances.
arXiv:2610.19041v1 Announce Type: new Abstract: Understanding the dynamics of language acquisition in Large Language Models (LLMs) is crucial for uncovering how statistical representations evolve into structured linguistic capabilities. However, most existing studies focus primarily on fully trained models, leaving the developmental trajectory across intermediate training stages largely underexplored. In this work, we leverage intermediate checkpoints from open-source models (e.g., Pythia and OLMo) under teacher-forcing evaluation to systematically investigate language acquisition across training steps and model scales. We focus on four core characteristics: morphological structure acquisition, embedding drift, repetition dominance, and co-occurrence effects. Our findings reveal that models acquire morphological structures well before semantic embeddings stabilize. Furthermore, we show that training dataset size has a positive impact on divergence recognition, while co-occurrence during pre-training and repetition during inference have a negative impact on divergence recognition and associative link generation.
arXiv:2610.19042v1 Announce Type: new Abstract: Understanding the mechanism behind why diffusion models memorize their training data remains an open question in generative modeling. In this paper, we examine this question from two perspectives: (a) the model-level perspective concerning the onset of memorization in a model during training, and (b) the sample-level perspective concerning the proclivity of an individual sample to be memorized by a given model. We show that the so-called input loss curvature, or the Frobenius norm of the Hessian of the diffusion model's training loss, is an effective metric for quantifying both perspectives on memorization. In particular, we empirically demonstrate that input curvatures averaged across training and validation samples can identify when a model is likely to start regurgitating its training data when tracked over training time. However, this metric is not sufficient for measuring an individual sample's likelihood of being memorized. To address this perspective, we introduce a counterfactual definition of memorization in diffusion models, extending the analogous notion from supervised learning proposed by [Feldman, 2019]. We prove that this counterfactual memorization is controlled by the input curvature of the leave-one-out model, thus establishing a direct theoretical link between a sample's local loss landscape and its generation
arXiv:2610.19043v1 Announce Type: new Abstract: Because its binary optimization landscape contains exponentially many local optima, MAX-CUT is highly sensitive to initialization. We study Particle Polynomial Relaxation (PPR), a moment-based nonconvex continuous reformulation possessing an advantageous optimization landscape. We warm-start PPR with Combinatorial Multigrid (CMG), a spectral graph-coarsening method that produces structure-aware initial solutions in near-linear time without training data. On \texttt{t2g20} ($n=400$), benchmark instance with known exact optimum, the combined CMG+PPR pipeline reaches $97.5\%$ of optimum on average and $98.4\%$ on the best run. An extended variant with discrete local-search refinement reaches the published optimum on all sixty Biq Mac instances evaluated by a recent neural branch-and-bound method. Using a sparse CSR representation, the same approach scales to G-set instances with up to $20{,}000$ vertices reducing memory requirements by up to $3333\times$ while maintaining a consistent improvement over the CMG warm start. Gains are largest on sparse weighted graphs; on dense graphs we complement the pipeline with spectral sparsification.
arXiv:2610.19046v1 Announce Type: new Abstract: Information-theoretic exploration is of primary interest in methodological studies of reinforcement learning (RL) and computational cognitive neuroscience, while the established RL theory builds regret guarantees on confidence sets. This situation leaves open the conditions under which the information-driven exploration found in nature is more advantageous than the exploration of the established RL theory. We put the state-of-the-art methods of these two paradigms, Active Inference (AIF) and Bayes-UCBVI, on an equal footing: both act through the same state abstraction of a tabular MDP with $S$ states, and their greedy forms differ only in the exploration term. We find that AIF's information gain decays too fast to serve as a confidence width, locking greedy agents that explore by it out of the optimal action. Calibrating the information gain by a square root yields calibrated AIF, which attains regret of order $\sqrt T$ for an exact abstraction, but no better guarantee than Bayes-UCBVI for a fixed reward. When an adversary chooses rewards from the agent's data, Bayes-UCBVI's value-specific widths lock out, whereas calibrated AIF pays a factor $\sqrt S$, which no goal-memoryless agent avoids on some MDP whose start states the adversary also chooses. Calibrated information gain thus
arXiv:2610.19053v1 Announce Type: new Abstract: Inference of phylogenetic trees from sequences plays a central role in understanding evolutionary relationships, with applications ranging from tracking pathogen spread to reconstructing the history of life. Conventionally, practitioners obtain posteriors over trees using likelihood-based methods like MCMC. However, likelihoods are only available for simple evolutionary models with restrictive assumptions. For realistic evolutionary models, inference using conventional methods is prohibitively expensive, inaccurate, or even impossible. In practice, practitioners settle for using as flexible a conventional method as possible, even though they expect it is misspecified. In principle, we could use simulation-based inference: simulate tree and sequence data from an evolutionary model and train a neural network to predict the posterior over trees given sequences. However it is a mathematical challenge to represent and train complex posterior distributions over trees. Here we present a flexible family of conditional generative models over trees. Our models iteratively build trees using three natural paradigms -- top-down, middle-out, or bottom-up -- and are trained using a discrete diffusion framework. For real and synthetic datasets of up to $65$ taxa and $>10^5$ tokens, our models recover MCMC posteriors much more accurately than the previous state-of-the-art simulation-based method Phyloformer 2. Finally, we
arXiv:2610.19064v1 Announce Type: new Abstract: Training large language models (LLMs) across geographically distributed and poorly interconnected compute pools or data centers has become a topic of significant interest. This has led to increased study of local optimization methods such as DiLoco for LLMs, especially those that use local (or inner) adaptive or preconditioned optimizers, which are critical for high-performance LLM training. However, a central challenge remains: it is well known that increasing the number of model replicas (replica scaling) while fixing the total training budget leads to monotonically decreasing performance. Existing work has empirically demonstrated that the choice of inner optimizer (Muon v.s. AdamW) can significantly improve this trend, but offers only limited explanation of the performance difference. In this work, we consider a range of inner-optimizers and identify two important factors that impact replica scaling: (1) the covariance structure of the pseudo-gradients and (2) the impact of batch size on the pseudogradient's noise scale. Based on these insights, we theoretically and empirically demonstrate that whitening-based pre-conditioning is a powerful inner-optimizer desideratum. Our empirical evaluation extends the results to reveal that whitening-based inner-optimizers achieve strong replica scaling (for 8-96 replicas), with performance relative to DP improving as parameters and data
arXiv:2610.19074v1 Announce Type: new Abstract: Reliable uncertainty quantification remains an important challenge in AI. Hierarchical Bayesian methods provide a principled framework for this by representing unknown quantities through posterior distributions. Joint inference of neural-network parameters and prior hyperparameters is challenging for conventional Markov chain Monte Carlo (MCMC) methods due to strong dependencies. In this work, we introduce the multilevel particle marginal Metropolis-Hastings (MLPMMH) method, which combines pseudo-marginal inference for the hyperparameters with coupled sequential Monte Carlo (SMC) across hierarchy of network-width truncations for conditional parameter inference. The hierarchy is induced by a trace-class neural network (TNN) prior with width-dependent decay, motivated empirically by the compressible structure observed in trained neural-network parameters. Under standard multilevel coupling assumptions, we establish that MLPMMH achieves mean-square error (MSE) $\mathcal{O}(\varepsilon^2)$ at expected computational cost $\mathcal{O}(\varepsilon^{-2})$, and verify the predicted rate on a Bayesian regression problem. To address larger-scale applications, we further introduce S-MLPMMH, a practical approximation that replaces the exact sampling components with a PCA-based hierarchy and scalable Bayesian Monte Carlo. Experiments on MNIST demonstrate competitive predictive performance and uncertainty quantification while exploiting the parallel structure of the approximation. Software has been made publicly available at https://github.com/submission-code-anon/mlpmmh-anon.
arXiv:2610.19080v1 Announce Type: new Abstract: Reinforcement learning (RL) has substantially improved the reasoning of autoregressive and discrete-diffusion language models. Language models that generate continuous token embeddings are emerging as a strong alternative, but RL post-training for them remains understudied. We propose \method{}, a post-training framework for continuous flow language models. Such a model denoises token embeddings over multiple steps and decodes them into discrete tokens only at the last step. To obtain pathwise gradients, which backpropagate through continuous actions and have much lower variance than REINFORCE, we introduce a critic that estimates the value of intermediate token embeddings, bypassing the non-differentiable decoding step. The critic must also keep track of the value function as the policy changes; to this end, we design a critic that predicts a value from every token representation and improves policy optimization. Across four reasoning tasks, \method{} reliably improves a continuous flow language model through RL post-training and outperforms baseline methods of the same type.
MLX on Mac with Apple silicon lets AI researchers and developers experiment locally with the latest models and methods in a private environment. The open-source array framework leverages the unified memory architecture of Apple silicon, enabling anyone to run new inference and fine-tuning methods on their own hardware and explore other AI techniques. In a previous post , we highlighted the advantages of the M5 architecture and its GPU Neural Accelerators.
Multimodal agents commonly generate freeform reasoning before each action. For small models, limited model capacity can result in lengthy reasoning that provides little useful guidance for action generation while incurring substantial inference cost. To address this challenge, we introduce Selection-based Structured Reasoning (SSR), a framework that reformulates reasoning as selection instead of open-ended generation. SSR represents recurring high-level reasoning as pre-specified, reusable natural-language candidates. At each turn, the model selects from the reasoning candidates based on their…
Tool-augmented LLM agents discover relevant APIs from large registries before planning execution, yet finite context windows prohibit injecting all tool definitions into a single prompt. The dominant approach, which we term Retrieve-then-Plan (RtP), embeds the user query and retrieves similar tools via approximate nearest-neighbor search. We study an alternative Plan-then-Retrieve (PtR) paradigm in which the LLM first generates Abstract Tool Stubs (hypothesized function signatures describing needed capabilities) which then serve as retrieval queries against the registry. Evaluating on…
暂无摘要
暂无摘要
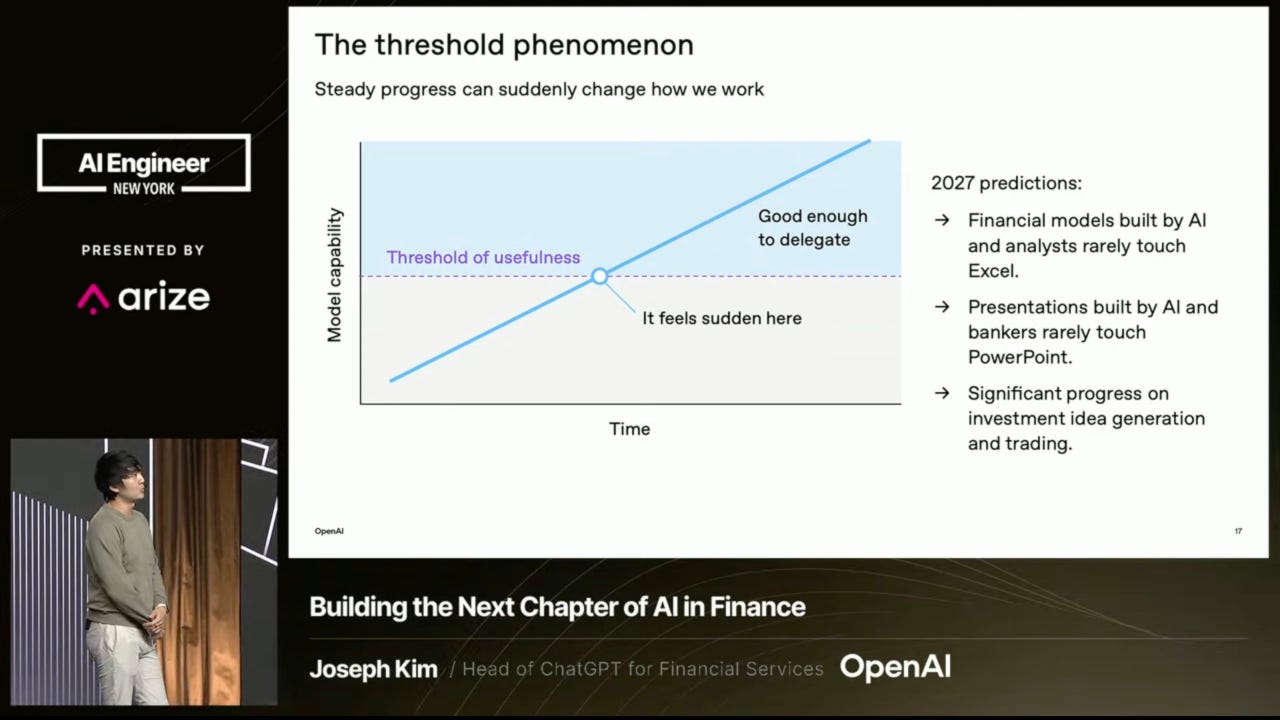
At AI Engineer New York, frontier labs and financial firms explored how to give agents useful autonomy while keeping consequential decisions under control.
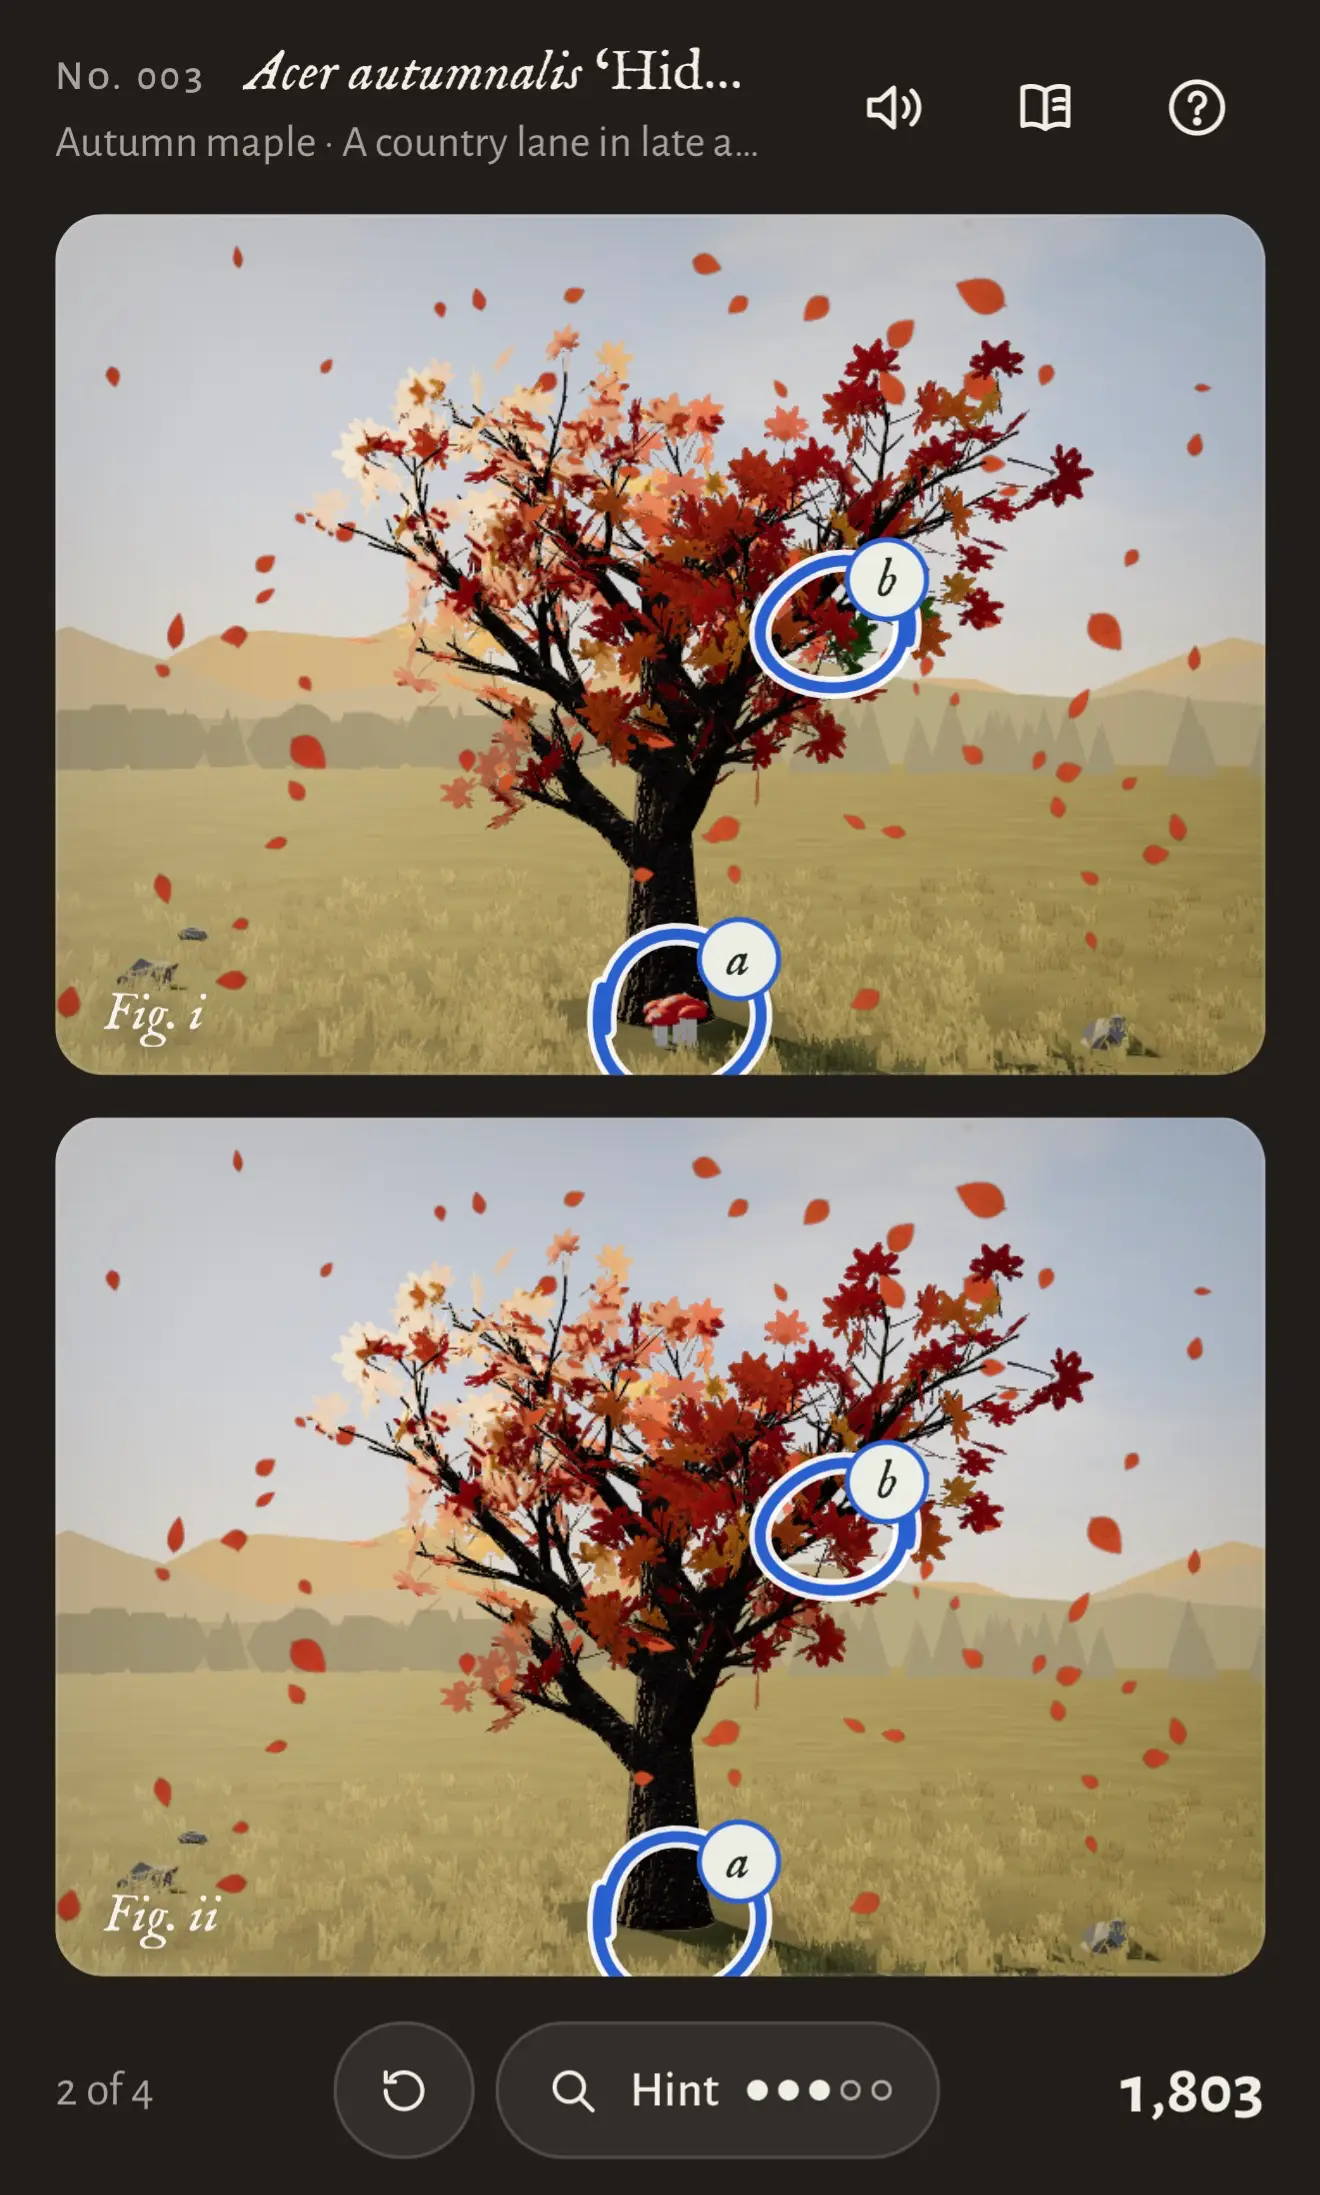
Tool: Tree Appreciator Another game experiment with Claude. This one used the default Claude iPhone app (chat mode, not Claude Code mode), where I prompted Claude Opus 5.5 Max with: Build a three js game called "Tree appreciator" - it shows you two algorithmically generated trees and the game mechanics is about appreciating the differences between them. Think hard about how to make sure it is both fun and beautiful. Somewhat embarrassingly given my recent talk , I've found that telling Opus 5.5 "make sure it is fun" works uncomfortably well. In this case Claude crunched for 3 hours and 7 minutes before retuning a cosy little spot-the-difference game with music and animation and achievements that's quite compelling to play. Tags: game-design , javascript , ai , generative-ai , llms , claude , vibe-coding , three-js
How Leash Bio tamed DELs, the assay that traumatizes everyone, and used the data to catch cheating models. And why that same data is perfect for AI agents learning to think like chemists.
In September, we experienced two incidents that resulted in degraded performance across GitHub services. The post GitHub availability report: September 2026 appeared first on The GitHub Blog .
Our new repo star history API now provides trends without returning individual identities or requiring unbounded database work. These are the engineering tradeoffs we made. The post From 2,500 requests to 24: Rebuilding star history without the stargazers appeared first on The GitHub Blog .
Earlier this year, we shared an update on our election safeguards. Here, we outline how we’ve continued to strengthen these safeguards ahead of this year’s US midterms.
Containment and monitoring failures are to blame for AI hacking reports: experts
AWS License Manager now supports in-place upgrades for EC2 Ubuntu LTS (Long Term Support) instances to Ubuntu Pro available on AWS Marketplace. This allows customers to strengthen their security posture and meet compliance requirements without rebuilding their fleet or migrating workloads to a new instance or AMI. With an Ubuntu Pro subscription, customers receive security patches for up to 10 years — extendable to 15 years with the Legacy add-on. This coverage extends beyond the base OS to thousands of additional packages, including widely used open-source applications such as NGINX, PostgreSQL, MongoDB, and Redis. Ubuntu Pro also supports Kernel Livepatch, which applies critical kernel security fixes without rebooting to minimize downtime. With this launch, customers, who have an existing Canonical Ubuntu Pro subscription through AWS Marketplace, can upgrade directly during the conversion workflow. Customers who do not yet have a subscription can subscribe to Canonical Ubuntu Pro from within the AWS License Manager console. The new feature is available in all commercial regions where AWS License Manager is available. To get started, navigate to the AWS License Manager console and the AWS License Manager User Guide .
Amazon SageMaker Studio now lets new customers sign up with their Google, GitHub, or Apple credentials and land inside a fully configured Studio environment - no traditional AWS account setup, no credit card, and no console navigation required. Previously, new customers who discovered a model on Hugging Face or an AWS product page had to complete a multi-step AWS account creation process, provide a credit card, navigate the AWS Console to find SageMaker AI, configure an environment, and set up IAM permissions before they could begin working. With earlier launches, we reduced environment setup to twenty seconds, pre-configured model customization permissions, and introduced deep links from Hugging Face and AWS product pages so customers could land directly inside Studio with a model pre-loaded. Now, with social sign-in, new customers complete a simplified sign-up using an existing identity, receive free credits as part of the AWS Free Tier with no credit card required, and arrive inside a ready-to-use SageMaker Studio environment where they can immediately fine-tune, evaluate, and deploy foundation models. Customers can invite team members by email, and collaborators sign in with their own social credentials to access the shared Studio environment, including shared models, notebooks, and endpoints without configuring
AI is mass decompiling games. That's both awesome and scary. Indie game developer Popcar talks about the recent wave of AI-powered decompilation of existing games, enabling weird mashups between existing games, and producing a boom in game preservation projects to get old games working on new hardware (often in a browser using WebAssembly). I like how this piece captures both the positives and the negatives of this new development: Most people already realized the scary part by now. If AI can decompile games and software, then the entire tech industry is about to explode. Anybody can decompile other software and use it any way they'd like, and nobody can stop them. Companies can steal from competitors. Your paid game or app can be open-sourced against your will. This isn't exclusive to old video games, we can apply this to any software. [...] This is also a big win for preservation. Old games can be ported, modified, enhanced, and made much more easily accessible than before. [...[ With console makers going all in on digital and games becoming entirely unplayable due to servers shutting down, this is fantastic news. We could own software we bought regardless of what the company thinks.

General Science
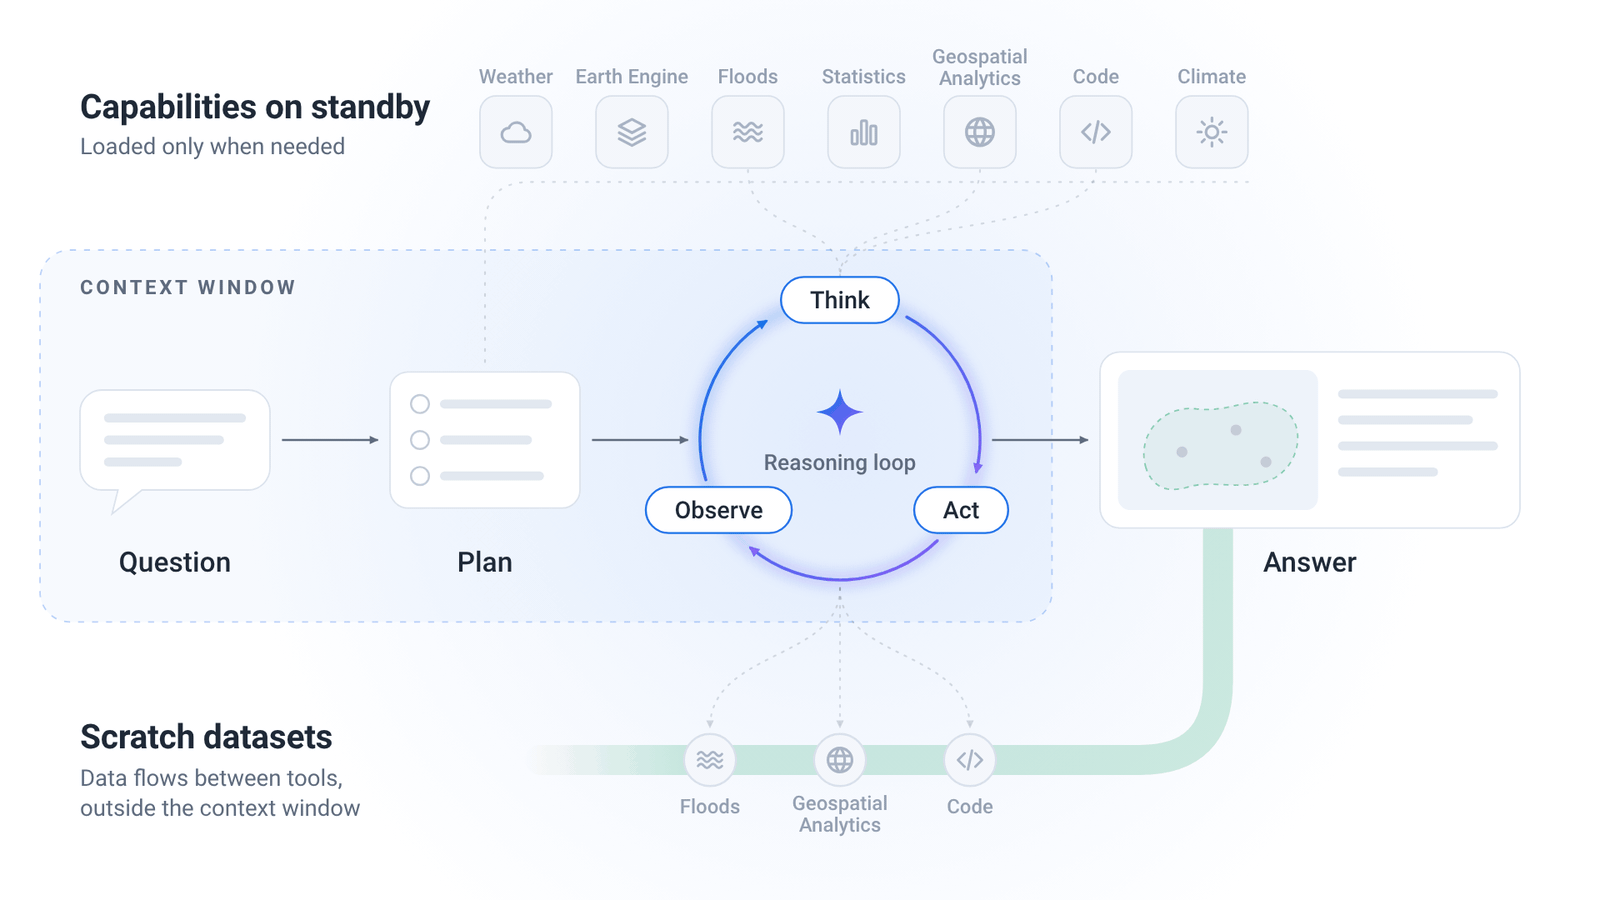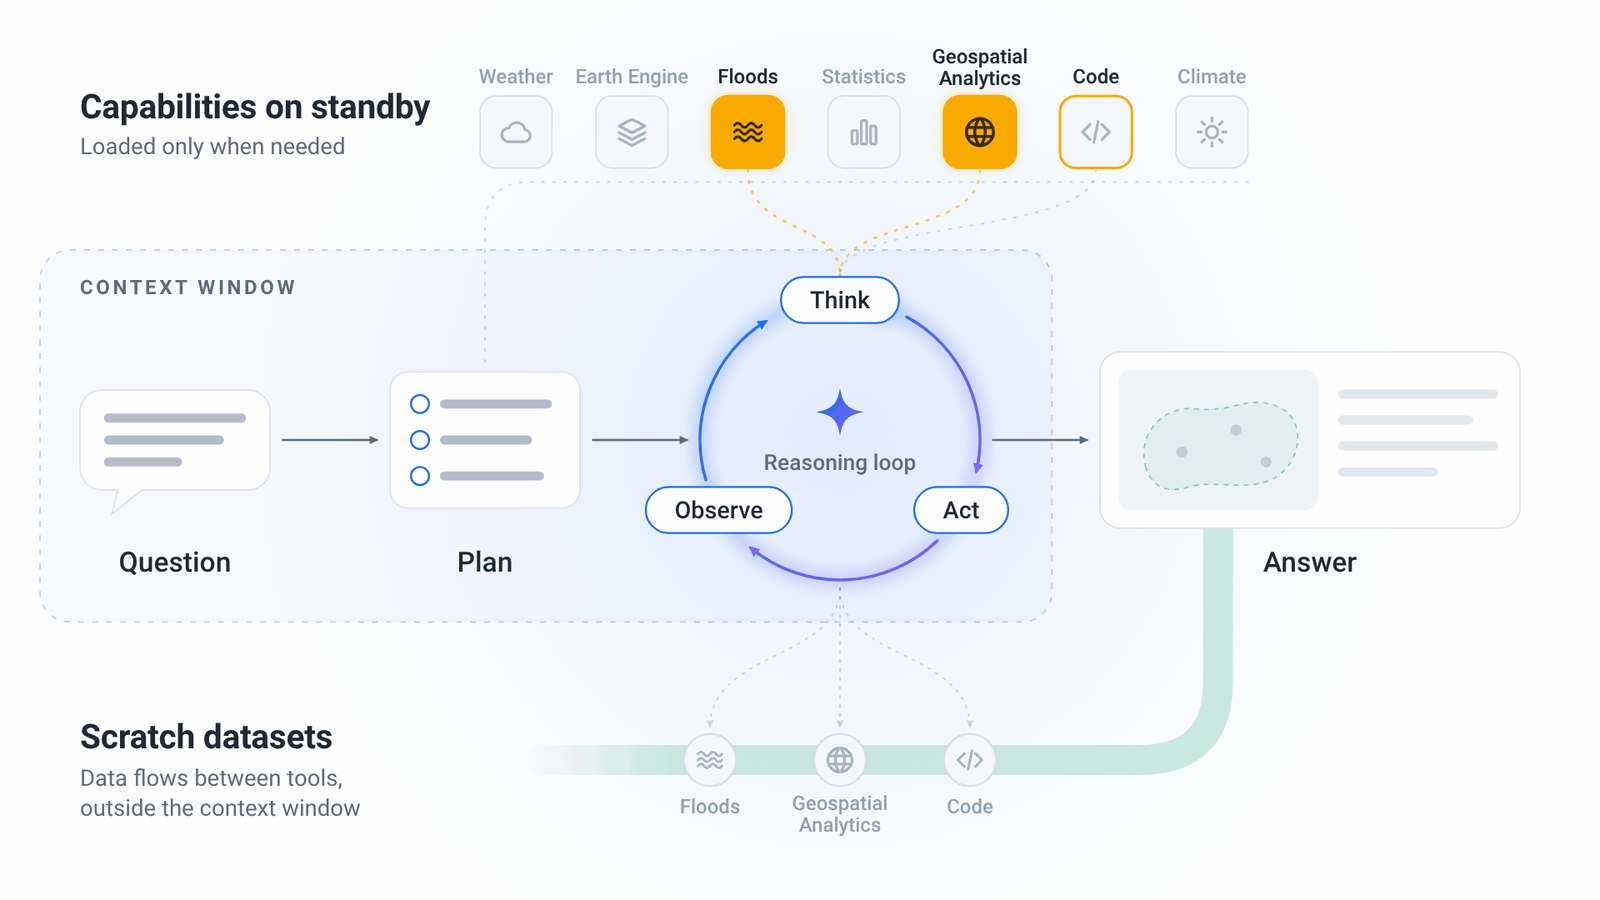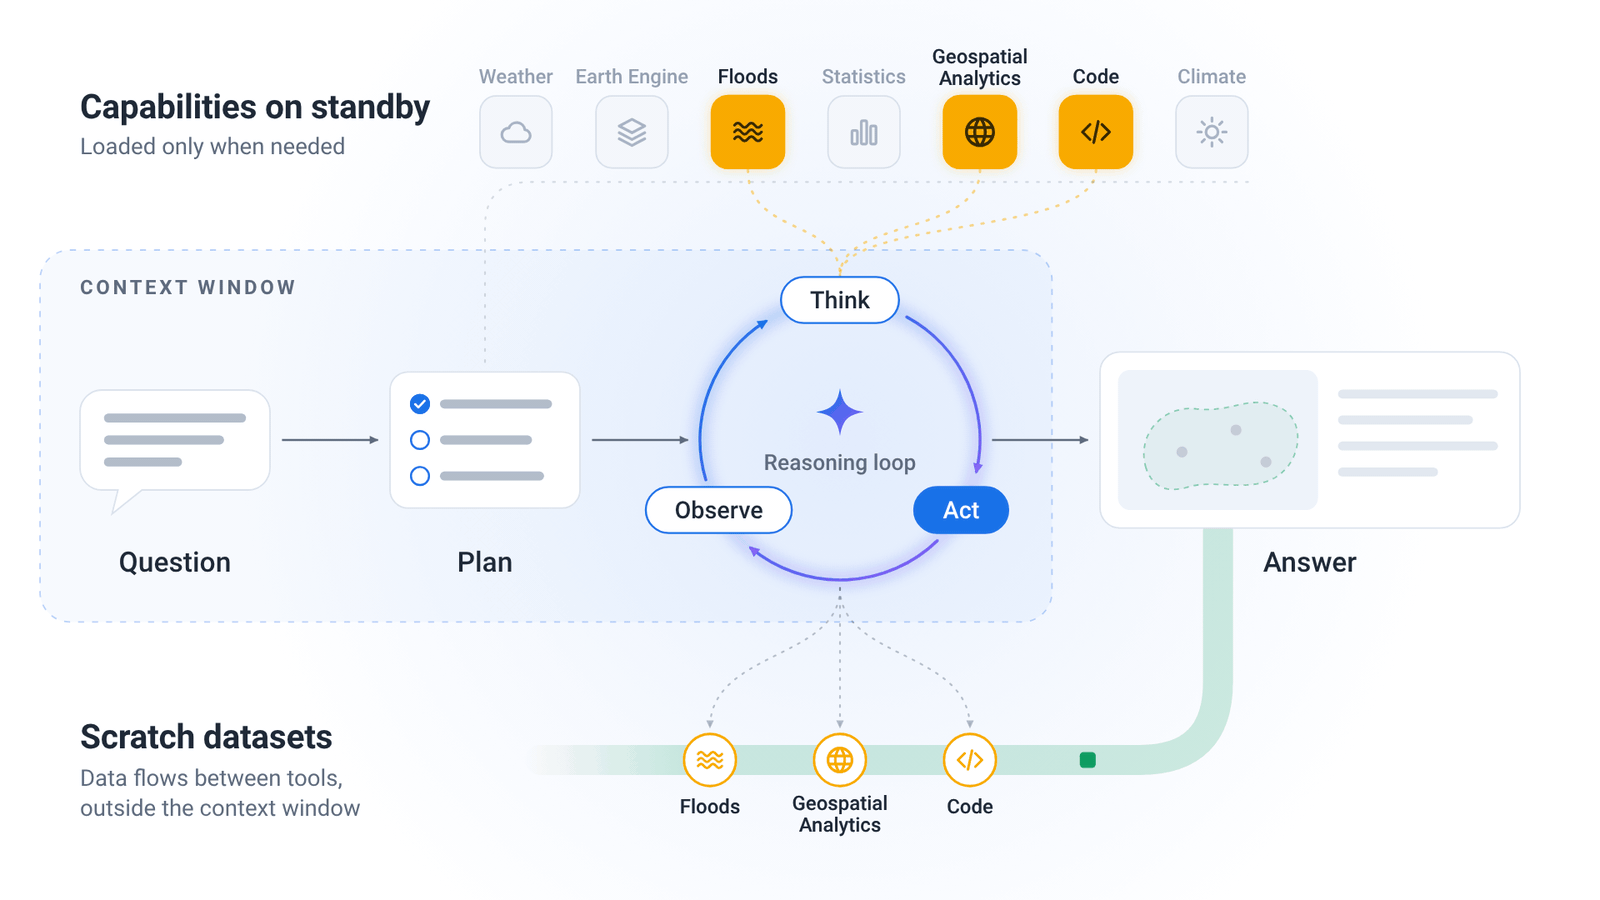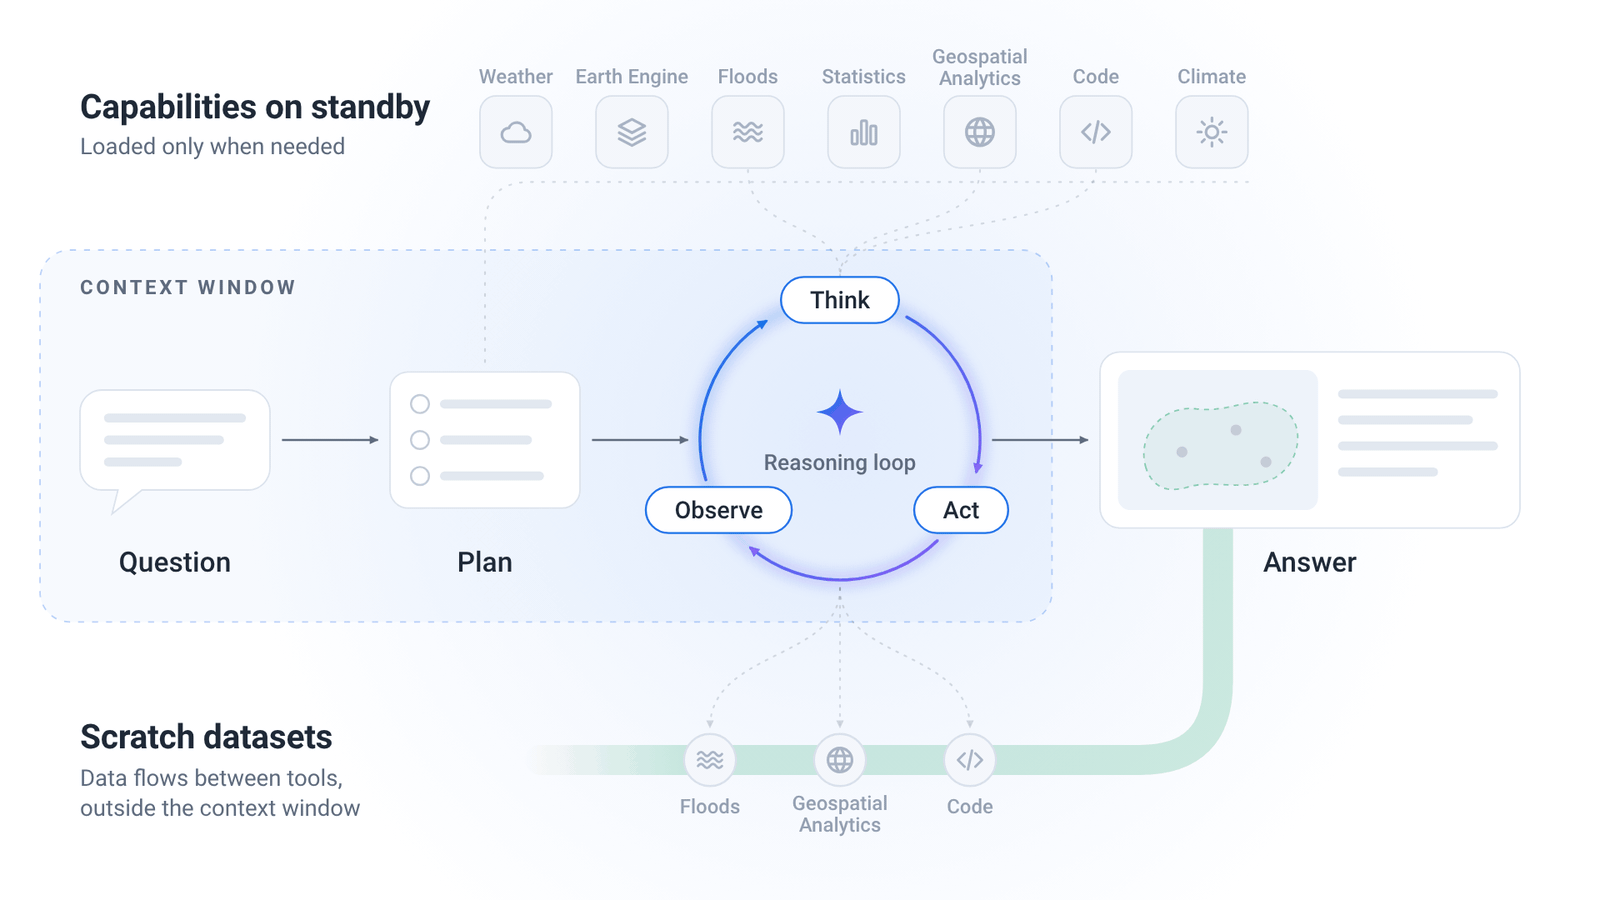
Earth AI
General Science
暂无摘要
Today, AWS HealthOmics introduces the resource fallback directive for tasks in your Nextflow workflows, enabling you to define an ordered list of preferred accelerator types, including an option to fallback to CPU instances. Researchers and bioinformaticians can use this directive to reduce time spent diagnosing and resubmitting runs due to accelerator constraints and keep production workflows running. AWS HealthOmics is a HIPAA-eligible service that helps healthcare and life sciences customers accelerate scientific breakthroughs at scale with fully managed bioinformatics workflows. With resource fallback for Nextflow workflows, you can prioritize your preferred accelerator for your task. When your preferred accelerator is unavailable, HealthOmics automatically moves through your specified alternatives in the fallback without resubmission. Each accelerator profile has a configurable timeout, giving you control over how long HealthOmics searches for that accelerator before moving to the next. Shorter timeouts help you move quickly through the fallback order, while longer timeouts increase the probability of reserving your preferred accelerator. You can also include a CPU profile as a final fallback to increase the likelihood of your task reserving an instance. You can now use resource fallback for Nextflow workflows in all AWS HealthOmics Regions: US East (N. Virginia, Ohio), US West (Oregon),
See how Amp pushes the frontier of what agents can do with GPT-6 Astra, Ultrafast, GPT-Live-1, and Sign in with ChatGPT.
With OpenAI Daybreak, SentinelOne cuts weeks of malware analysis to hours, creating capacity to investigate more threats.
Anthropic opens its fifth Asia-Pacific office in Singapore and signs an MOU with the government on AI safety, evaluation, and responsible adoption.
AWS Backup now supports Amazon FSx for Lustre, Amazon FSx for NetApp ONTAP, Amazon FSx for OpenZFS, and Amazon FSx for Windows File Server in the Asia Pacific (New Zealand) Region. With this launch, you can use AWS Backup to centrally automate and manage data protection for your Amazon FSx file systems in the Asia Pacific (New Zealand) Region, alongside your other supported AWS resources. You can create policy-based backup plans to schedule backups and apply retention rules, store backups in encrypted vaults, and restore file systems when needed. This helps you meet business continuity, disaster recovery, and regulatory compliance requirements from a single, centralized service. To get started, visit the AWS Backup console, AWS Command Line Interface (CLI), or AWS SDKs. For a complete list of supported Regions and features, visit the AWS Backup documentation . To learn more about AWS Backup, visit the product page and pricing page .
Amazon RDS Proxy , a fully managed, highly available database proxy for Amazon Relational Database Service (RDS) , now supports Amazon RDS for SQL Server instances running major version 2022. Amazon RDS Proxy sits between your application and the database to pool and share established database connections, improving database efficiency and application scalability. For Amazon RDS for SQL Server Multi-AZ databases, RDS Proxy automatically connects to the standby database instance during a failure, preserves application connections, and helps reduce failover times by up to 83%. RDS Proxy supports standard IAM authentication for SQL Server, where your applications authenticate to the proxy using AWS Identity and Access Management (IAM) and RDS Proxy manages database connections using credentials stored in AWS Secrets Manager. You can enable Amazon RDS Proxy for your SQL Server 2022 database in a few steps on the Amazon RDS console, then connect by pointing your application to the RDS Proxy endpoint. To get started, see our documentation .
With GPT-6 Astra and GPT-6.1 Sol, Codex, and Daybreak for cybersecurity, this AI lab builds agents that focus for days and improve with use.
Block is building AI-powered security with OpenAI. Its security team investigates threats faster and proposes patches in minutes.
Across industries, the U.K. is putting the full stack to work. The scale of deployment is growing fast, from enterprises transforming their businesses to startups solving some of the planet’s hardest problems. NVIDIA is putting that principle into practice, including through a five-year, $250 million compute commitment to strengthen the U.K.’s agentic safety and security […]
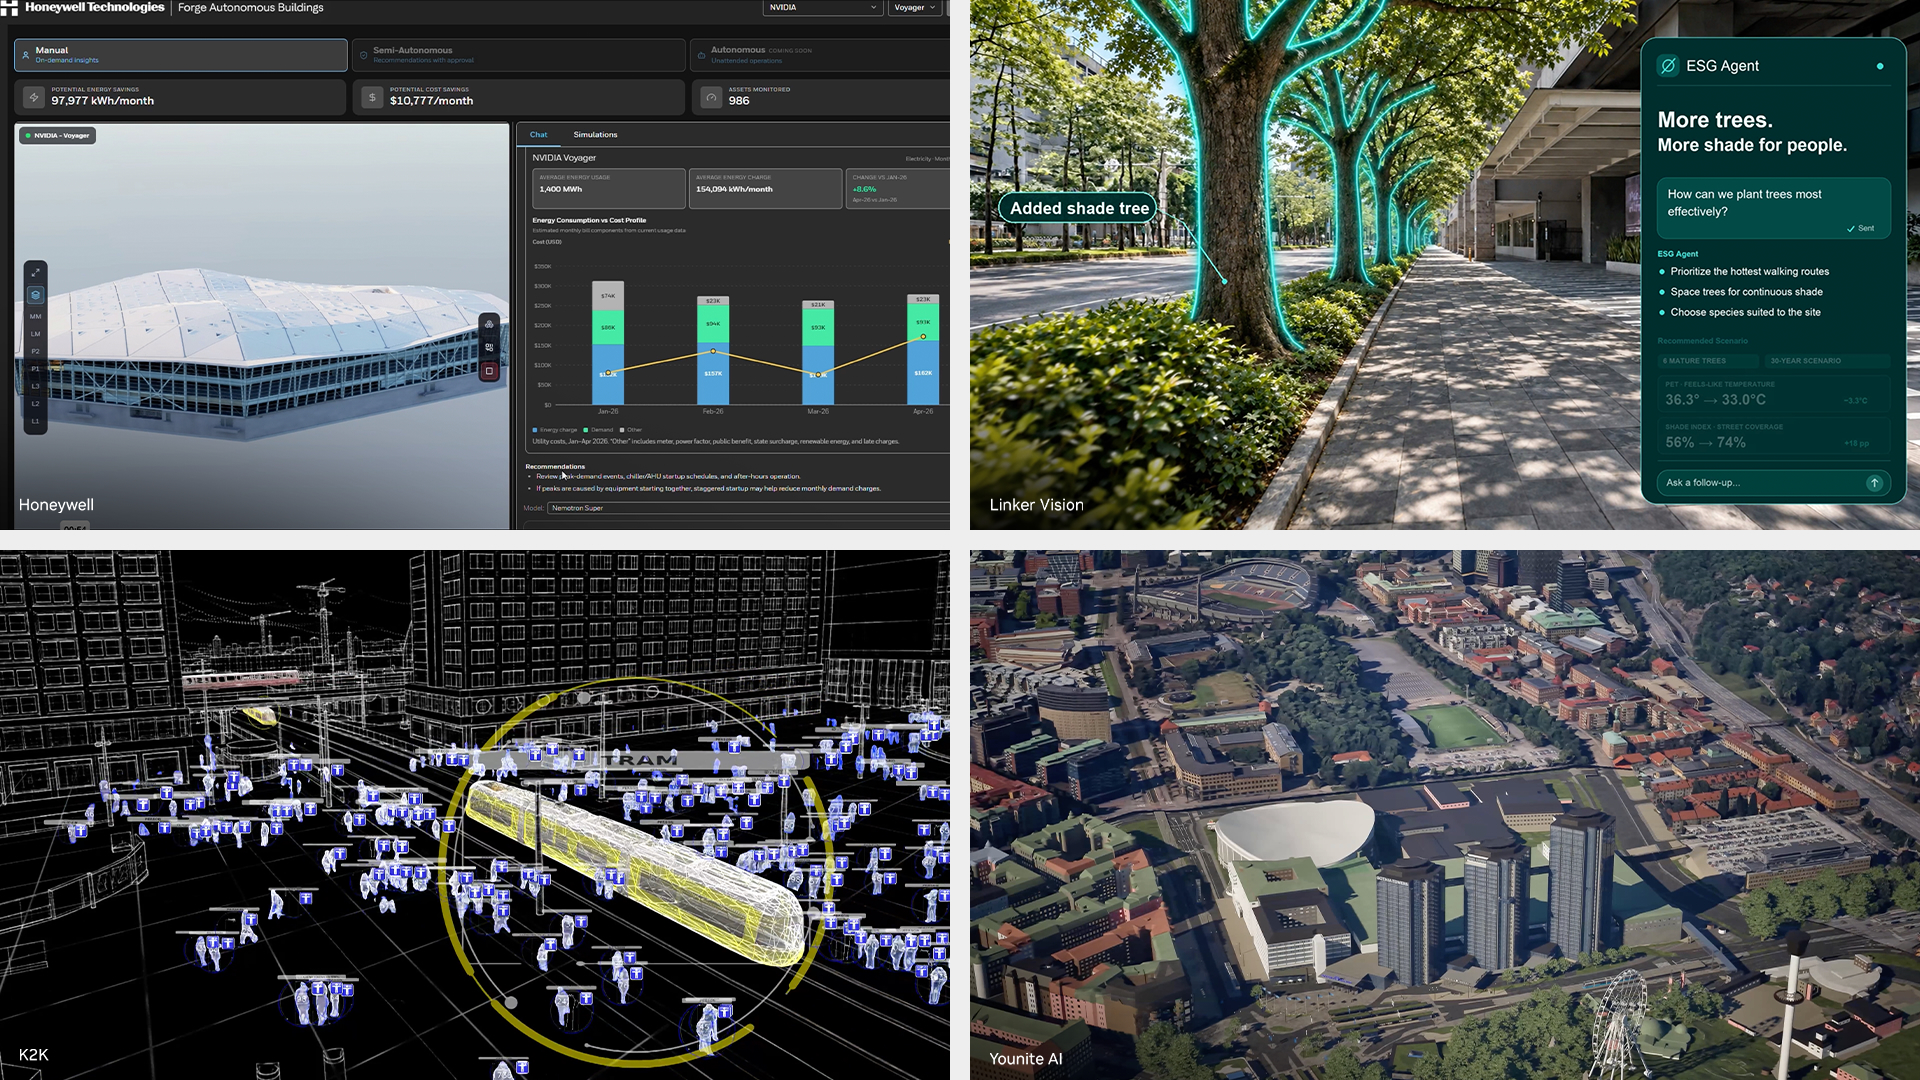
Keeping a city running means making decisions that affect residents every day — from when to repair a road to how to use energy more efficiently. Across the EMEA region, cities and local software, infrastructure and integration partners are using NVIDIA accelerated computing to build physical AI agents and digital twins that help teams make […]
Gemini 4 Argon went GA today, but we already gave it title story 2 weeks ago and most benchmarks, like CursorBench, simply independently confirm their claims.
Amazon S3, including S3 Tables and S3 Vectors, is now available on the Vercel Marketplace and v0 by Vercel. Developers can create and connect S3 resources in seconds without leaving their development environment, getting the durability, scalability, and performance of S3 through Vercel's streamlined provisioning workflow. Millions of customers rely on S3 for low-cost, high-performance storage to power web and AI applications, but until now provisioning it from Vercel required navigating to the AWS Management Console. Now, S3 integrates directly into the Vercel developer experience, automatically handling resource provisioning and connection configuration. You can choose from S3 general purpose buckets for virtually any use case, S3 Tables for fully managed Apache Iceberg tables optimized for analytics workloads, or S3 Vectors to natively store and query vectors at scale. New AWS accounts created through Vercel include $100 in credits valid for up to six months, usable across Amazon S3, Amazon OpenSearch Serverless, and AWS Database services. Existing AWS customers can link their account to use S3 with their Vercel projects. Amazon S3 on Vercel is now available in all AWS Regions where Vercel is available. To get started, read the AWS News Blog , visit AWS on Vercel Marketplace , or
arXiv:2610.14005v1 Announce Type: new Abstract: Under the accelerated pace of AI development, any benchmark whose difficulty is calibrated with humans or current AI systems becomes circular, or saturates soon. How can we then evaluate machines that may become more capable than the current machines and the people who write the tests? One answer to the question hinges on inverse problems, inductive inference questions for which difficulty depends on the complexity of the underlying mechanism, given the observations and the previous knowledge. Levin's Kt, a computable variant of Kolmogorov complexity, puts a theoretical upper bound to that difficulty, balancing the simplest representation encoding for the mechanism and the logarithm of the time steps to run that mechanism. Previous tests derived from Levin's Kt, such as the original C-test, are based on minimalistic Universal Turing Machines (UTM), capable of very limited representations and no previous knowledge. Reasoning large language models (LLM) are UTMs that capture a compendium of human culture as knowledge, using prompts as natural language programs. This paper presents the first test based on Levin's Kt with LLMs as representational machines. Fresh test items can be produced at high difficulties, estimated in a ratio scale measured in bits, before any
arXiv:2610.14115v1 Announce Type: new Abstract: Large language models have significantly lowered the barrier to writing code. Naturally, this has also led to the development of data science agents that promise automating the design and execution of data science from task formulation to model development. Existing evaluations of agentic data science (agentic DS) assess downstream predictive performance and code correctness, providing preliminary insight in agentic DS capabilities. We argue that these evaluations overlook the fundamental principles of data science: methodological data science- and domain knowledge. As such, only assessing downstream performance masks methodological failures such as data leakage and inappropriate validation, limiting the development of robust agentic DS systems. In this paper, we evaluate agentic DS beyond accuracy from three different angles: 1) a large-scale analysis of failure modes in common agentic DS frameworks and models across 220 data science tasks, 2) a reusable and extensible test suite with curated data science tasks that test for six specific failures in a controlled manner, and 3) a qualitative assessment of agentic DS pipelines against expert solutions on Kaggle competitions. We find that the majority of agentic solutions contain at least one failure mode despite the complexity of agentic harness or model capacity.
arXiv:2610.14118v1 Announce Type: new Abstract: The rapid advancement of Large Language Models (LLMs) has driven their deployment toward general-purpose harness environments, where LLM-based agents operate in sandbox workspaces and interact directly with file systems and shells. While numerous post-training pipelines exist for tool-use agents, their counterparts for harness-based agents remain scarce and are predominantly one-shot and teacher-dependent: a stronger external model synthesizes tasks and collects trajectories, the target agent is trained once, and evaluation results are consumed by human researchers rather than fed back into the loop. Such pipelines are inherently bounded by the capability of the external model and the scope of human prior, leaving no room for self-improvement. To address these limitations, we propose ClawLoop, a framework that enables self-improving without any external teacher model and with minimal prior dependencies. ClawLoop composes three phases into a self-sustaining cycle: Task Synthesis, which generates a diverse pool of training tasks via two complementary construction routines, applies diagnosis-conditioned difficulty growth followed by both agent-free and agent-based task validation; Training, which updates the agent via SFT and/or RL; and Diagnosis and Feedback, which analyzes the agent's rollout behaviors to produce a capability analysis report that will be used as feedback for task
arXiv:2610.14146v1 Announce Type: new Abstract: Long-horizon terminal benchmarks measure whether an agent can sustain progress through extended workflows with process rewards, not only whether its final state passes a binary check. We present Long-Horizon-Terminal-Bench 2.0 (LHTB 2.0), an extension of Long-Horizon-Terminal-Bench that preserves its 46 original tasks while correcting task and evaluation-infrastructure defects and extending 31 tasks. LHTB 2.0 contains 77 tasks across 13 domains and eight task types. The extended tasks are produced through a systematic reconstruction-task pipeline. We start from a working scientific or engineering artifact, then use a parameterized reference implementation to generate multiple scenarios, reveal six as behavioral evidence, hold out three for evaluation, and use dense progress ladders to reward partial progress while preventing memorization of public outputs. We also extend the evaluation horizon from 90 minutes to three hours and record verifier checkpoints every 30 minutes, enabling direct measurement of sustained progress within a run. Across 1,145 scored model-task runs from 15 frontier models, GPT-6-astra leads with dense mean reward 0.69 and 37 tasks at R at least 0.95, followed by GPT-5.6-sol with dense mean reward 0.67 and 32 tasks at the same threshold. On the 30 reconstruction tasks, binary verifier scores average 0.221,